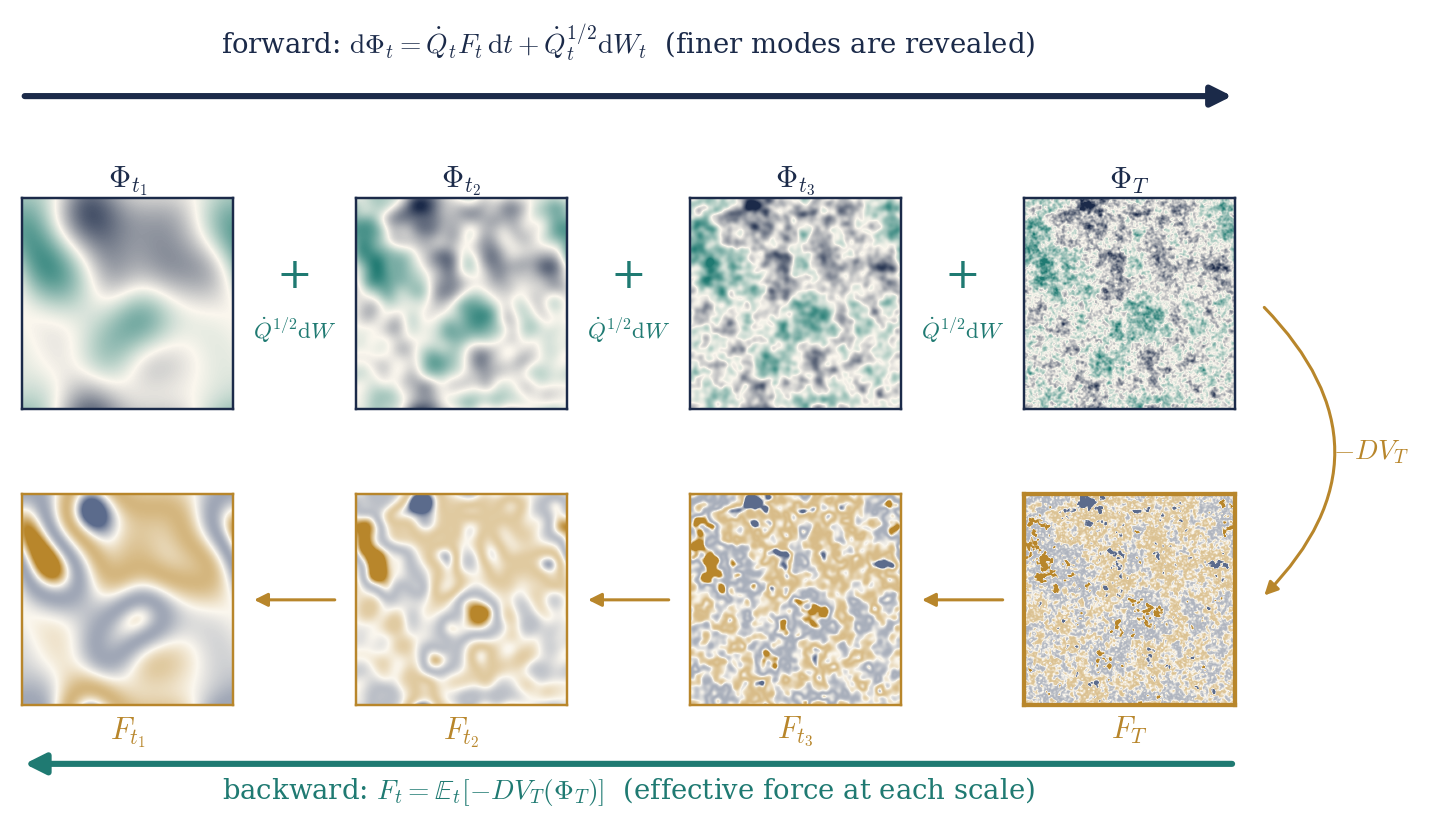
|
Figure 7.1. The forward–backward
structure of |
|
Abstract
Building on the scale decomposition and the stochastic observables of Lecture 3, we introduce interactions. The interacting measure can be generated in three ways: as a renormalisation group decomposition of the covariance, as an optimal control problem, whose dynamic programming equation is the Polchinski equation, and as a filtering problem: the field at resolution \(t\) is a noisy observation of the terminal field, the Polchinski process is this observation written in its own filtration, and backward in resolution its dynamics is linear, with Gaussian transitions, started from the interacting measure. The three views meet in one forward–backward system for a field and a force, and its natural coordinates are the force coordinates: the forward equation loses its drift, and the conditional covariance becomes the propagator. All this can be said in terms of forces, propagators and covariances. In the gradient case there is a parallel story for potentials: the value function generates the canonical transformation to force coordinates, the Legendre transform of the log-partition function of the filter gives the effective average action, and its flow is the Wetterich equation. We then discuss stochastic observables, the field equation at every resolution, whose noise is a filtered Gaussian noise and therefore sub-Gaussian, whatever the interaction (an observation which, as far as we know, is new, and which is the key input of the a priori estimates of Lecture 6), and the passage to infinite volume. The appendices contain the algebra of the flow, perturbation theory and counterterms, and the functional inequalities that follow from the localisation. The treatment is formal: we compute as if all objects were smooth and integrable, and we indicate where the real difficulties lie.
The results presented in Lectures 4–6 were obtained recently, with the use of AI, in collaboration with Sarah-Jean Meyer.
Introduction 3
Structure 3
What is formal 3
Conventions 3
Acknowledgements 3
Main lecture 3
7Three ways to generate the interacting measure 4
7.1Renormalisation: decomposing the covariance 5
The field as a process 5
7.2Optimal control: the Polchinski equation 6
The control problem 7
Euler–Lagrange equation \(=\) FBSDE 7
Entropy 7
Generating functionals 7
Pontryagin's maximum principle 7
The costate is a gradient 8
The Hamiltonian of the field 8
With noise 8
7.3Filtering: measuring the field 8
The terminal field as a hidden signal 10
Generation by denoising 10
7.4Where the three views meet 11
Exercises 12
8Force coordinates and potentials 12
8.1The force and a Burgers equation 12
8.2Removing the predictable drift 13
8.3The FBSDE in the forecast coordinate 14
A one-dimensional model: Burgers and Lax–Oleinik 15
8.4Conditional moments 16
Brascamp–Lieb and Cramér–Rao bounds 16
8.5Potentials: the value function as a generator 17
Phase space and Lagrangian graphs 17
The free action generates the shear 17
The value function generates the graph 18
No convexity is needed 18
8.6The Legendre transform and Wetterich's equation 19
Probabilistic meaning of \(\Gamma\) 20
8.7Variational meaning and the tree level 20
Constrained free energies 21
The tree level 21
Exercises 22
9Observables and field equations 22
9.1Observables of the interacting theory 22
Tangent observables 22
9.2The field equation at every resolution 23
The field equation for the forecast 24
9.3Gaussian bounds for the noise 25
The roughness of the noise 25
Control of the force 26
Consequence for \(\Phi^4_3\) 26
9.4Infinite volume 26
Differences of free energies 27
Exercises 28
Appendices: additional material 28
Appendix AAlgebraic structure of the Polchinski flow 28
A.1A semigroup of renormalisation maps 28
A.2Perturbation theory and counterterms 29
Exercises 30
Appendix BStochastic localisation 30
Why it is useful 30
B.1Log-Sobolev inequalities along the localisation 30
Entropy as quadratic variation 31
In terms of the conditional covariance 32
An application: the KLS conjecture 32
The connection with Bauerschmidt–Bodineau 33
Exercises 33
References ?
In Lecture 3 we decomposed the Gaussian free field along a resolution parameter and took as primary objects the stochastic observables: martingales in the filtration of finite-resolution measurements [BCG26]. In this lecture we introduce interactions, and we tell one story from three points of view: renormalisation, optimal control and filtering. See also [Pol84, BK87, Sal99, BBD24] for the renormalisation group side and [BG20, BG23] for the variational side.
Fix a finite volume \(\mathcal{M}=\mathbb{T}^d_L\) and a terminal resolution \(T < \infty\), which plays the role of an ultraviolet cutoff: the reference field \(X_T \sim \mu^{Q_T}\) is smooth. Let \(V_T\) be an interaction, a functional of smooth fields bounded below. Our main example is
| \(\displaystyle V_T (\varphi) = \int_{\mathbb{T}^d_L} \left[ \frac{\lambda}{12} H_4 (\varphi (x) ; c_T) + \gamma_T \hspace{0.17em} H_2 (\varphi (x) ; c_T) \right] \mathrm{d} x,\) | (7.1) |
with a mass counterterm \(\gamma_T\) to be fixed in Appendix A.2 (\(\gamma_T = 0\) for \(d = 2\)). The coupling is normalised by \(\lambda / 12\) so that the curvature of the quartic term is \(\lambda \varphi^2\), as in Lectures 5–6. The interacting measure at cutoff \(T\) is
| \(\displaystyle \nu_T (\mathrm{d} \varphi) = Z_T^{- 1} \mathrm{e}^{- V_T (\varphi)} \mu^{Q_T} (\mathrm{d} \varphi) .\) | (7.2) |
How does the Gaussian scale decomposition of Lecture 3 generate \(\nu_T\)? There are three answers.
Renormalisation (Section 7.1). Split the covariance into shells and integrate them out one at a time. At every resolution the field is again a Gibbs measure, and it is driven by an effective force.
Optimal control (Section 7.2). Steer the Gaussian field by a drift, at the least cost. The effective potential is the value function, and the Polchinski equation is the dynamic programming equation.
Filtering (Section 7.3). Observe the terminal field through noise, with increasing precision. The field at resolution \(t\) is the observation, the force is what it reveals about the terminal field, and backward in resolution the process has a linear dynamics with Gaussian transitions, started from the interacting measure.
Section 7.4 shows that the three constructions produce the same process. Throughout,
is the covariance still unresolved at resolution \(t\).
Decompose the covariance as in Lecture 3: \(Q_T = Q_t + S_t\), and correspondingly
with independent terms. Integrating out the second one defines the effective potential.
Definition
\(V_t\) is the interaction felt by the field at resolution \(t\) once the fluctuations between \(t\) and \(T\) have been integrated out: it is the Wilson effective action. At \(t = 0\), \(V_0 (0) = - \log Z_T\) is the free energy. Here is the first key fact.
Proposition
where \(\mathbb{P}_0\) is the law of the Gaussian process \(X\). Then \(\text{Law}_{\mathbb{P}} (X_T) = \nu_T\), and for every \(t \leqslant T\)
| \(\displaystyle \text{Law}_{\mathbb{P}} (X_t) = \nu_t, \qquad \nu_t (\mathrm{d} \varphi) := Z_T^{- 1} \mathrm{e}^{- V_t (\varphi)} \mu^{Q_t} (\mathrm{d} \varphi) .\) | (7.4) |
Moreover, the conditional law of \(X_T\) given \(\mathcal{F}_t\) is
Proof. Under \(\mathbb{P}_0\), \(X_T = X_t + (X_T - X_t)\) with an independent increment of law \(\mu^{Q_{T, t}}\). Hence \(\mathbb{E}_{\mathbb{P}} [G (X_t)] = Z_T^{- 1} \mathbb{E}_0 [G (X_t) \mathrm{e}^{- V_T (X_T)}] = Z_T^{- 1} \mathbb{E}_0 [G (X_t) \mathrm{e}^{- V_t (X_t)}]\). The conditional law follows in the same way.\(\Box\)
So at every resolution the field is again a Gibbs measure, with reference covariance \(Q_t\) and potential \(V_t\). The measure-valued martingale \((\mu_t^{X_t})_t\) goes from \(\nu_T\) at \(t = 0\) to \(\delta_{X_T}\) at \(t = T\): it is a stochastic localisation of \(\nu_T\) in the sense of Eldan [Eld23], adapted to the covariance profile [BBD24, BCG26].
Theorem
with \(\Phi_0 = 0\) and a \(\mathbb{P}\)-cylindrical Brownian motion \(W^{\mathbb{P}}\). In particular the effective force \((F_t)_{t \leqslant T}\) is a \(\mathbb{P}\)-martingale: an observable field of the interacting theory.
Proof. The density process is \(M_t := \mathbb{E}_0 [\hspace{0.17em} \mathrm{d} \mathbb{P}/ \hspace{0.17em} \mathrm{d} \mathbb{P}_0 |\mathcal{F}_t] = Z_T^{- 1} \mathrm{e}^{- V_t (X_t)}\), by Proposition 7.2. It is a martingale, so the drift in Itô's formula vanishes and \(\hspace{0.17em} \mathrm{d} M_t = - M_t \langle \mathrm{D} V_t (X_t), \dot{Q}_t^{1 / 2} \hspace{0.17em} \mathrm{d} W_t \rangle\). By Girsanov's theorem, \(W^{\mathbb{P}}_t = W_t + \int_0^t \dot{Q}_s^{1 / 2} \mathrm{D} V_s (X_s) \hspace{0.17em} \mathrm{d} s\) is a \(\mathbb{P}\)-Brownian motion, which is (7.6). Differentiating (7.3) gives \(\mathrm{D} V_t (\phi) = \mu_t^{\phi} (\mathrm{D} V_T)\), which is the second identity.\(\Box\)
Read as an equation for an unknown pair \((\Phi, F)\),
Here and below we drop the superscript and write \(W\) for the Brownian
motion driving the interacting field. No equation for the potential is
needed to state
|
|
Figure 7.1. The forward–backward
structure of |
The measure \(\nu_T\) also solves a minimisation problem. Perturb the Gaussian field by an adapted drift, and pay for the drift and for the interaction at the endpoint. The effective potential is the value function of this problem. Its equation in \(t\), which we first derive directly from (7.3), is the dynamic programming equation.
Theorem
with terminal condition \(V_T\).
Proof. \(u_t := \mathrm{e}^{- V_t} = \mathrm{e}^{\frac{1}{2} \Delta_{Q_{T, t}}} u_T\) is a Gaussian convolution, where \(\Delta_Q := \text{Tr} (Q \mathrm{D}^2)\). Since \(\partial_t Q_{T, t} = - \dot{Q}_t\), it solves the backward heat equation \(\partial_t u_t = - \frac{1}{2} \text{Tr} (\dot{Q}_t \mathrm{D}^2 u_t)\). Insert \(\mathrm{D}^2 u = (\mathrm{D} V \otimes \mathrm{D} V - \mathrm{D}^2 V) u\) and divide by \(- u\).\(\Box\)
The nonlinear term generates new, generally nonlocal, interactions (trees), and the trace term contracts pairs of fields with the covariance of the shell \([t, t + \mathrm{d} t]\) (loops). The substitution \(u = \mathrm{e}^{- V}\), which linearises the equation, is a Cole–Hopf transform: we come back to this in Section 8.1, and in Appendix A.
the field driven by the control \(u\) under the Gaussian reference \(\mathbb{P}_0\).
The following result is standard in the stochastic optimal control setting, see e.g. Fleming and Soner's book [FS06]. A useful non-Markovian generalisation is given by Boué–Dupuis [BD98].
Theorem
| \(\displaystyle - \log \mathbb{E}_0 [\mathrm{e}^{- V_T (X_T)}] = V_0 (0) = \inf_{u \in \mathbb{H}_a} \mathbb{E}_0 \left[ V_T (X^u_T) + \frac{1}{2} \int_0^T \|u_s \|^2 \mathrm{d} s \right] .\) | (7.9) |
The infimum is attained at the feedback control \(u^{\ast}_s = -
\dot{Q}_s^{1 / 2} \mathrm{D} V_s (X^{u^{\ast}}_s)\), and \(\text{Law}
(X^{u^{\ast}}_T) = \nu_T\). The effective potential is the value
function, and
Proof. (Verification.) For any \(u\), by
Itô's formula and
with \(\mathrm{D} V_t = \mathrm{D} V_t (X^u_t)\) and a martingale \(M\). Integrating and taking expectations,
So the cost is \(\geqslant V_0 (0)\), with equality iff \(u =
u^{\ast}\). With this control \(X^{u^{\ast}}\) solves the same SDE as
\(\Phi\) in
| \(\displaystyle u_s = - \dot{Q}_s^{1 / 2} \hspace{0.17em} \mathbb{E}_s [\mathrm{D} V_T (X^u_T)] = \dot{Q}_s^{1 / 2} F_s .\) | (7.11) |
This is
Bounds on \(\mathcal{W}_T (f)\) uniform in \(T\), for \(f\) in a rich class, give tightness, moment bounds and the identification of limits. For \(\Phi^4_3\) the naive problem does not have uniform bounds: the leading-order optimal drift \(u_s \approx - \frac{\lambda}{3} \dot{Q}_s^{1 / 2} : X_s^3\): has a divergent cost. One renormalises by the change of variables \(u = - \frac{\lambda}{3} \dot{Q}^{1 / 2} : X^3 : + r\). After it, and after further paracontrolled changes of variables, the singular terms are explicit polynomials in the Wick powers of \(X\), cancelled by the counterterms, and the residual functional is coercive. Its control in Besov and paracontrolled norms, uniformly in \(T\), is the construction of \(\Phi^4_3\) in [BG20]; see also [BG21].
Pontryagin's principle [PBGM62] says that along an optimal pair \((x, u)\) there is a costate \(p\) such that
The state runs forward from its initial value, the costate backward from its terminal value: a two-point boundary value problem. In the smooth case the principle is the first-order condition. If \(\xi = \partial_{\varepsilon} x\) is the variation of the state under \(u \to u + \varepsilon v\), then \(\dot{\xi} = \partial_x b \xi + \partial_u bv\), \(\xi_t = 0\), and the costate equation is exactly what makes \(\frac{\mathrm{d}}{\mathrm{d} s} \langle p, \xi \rangle = \langle \partial_x \ell, \xi \rangle + \langle p, \partial_u bv \rangle\). Integrating over \([t, T]\) and using the terminal condition,
So the costate is the Lagrange multiplier of the constraint \(\dot{x} = b\), and an optimal control is a critical point of the Hamiltonian.
Its characteristics are Hamilton's equations for \(H_{\ast}\), and along them \(p_s = - \mathrm{D} V (s, x_s)\): the costate is the sensitivity of the optimal cost to a displacement of the state, i.e. the force that the future exerts on the present.
is the Hamiltonian of a free particle with mass matrix \(\dot{Q}_s^{- 1}\): it does not depend on the state. Hence \(\dot{p} = 0\) and \(\dot{x} = \dot{Q}_s p\): the costate is conserved, and from \(t\) to \(T\) the state moves along the linear shear
| \(\displaystyle \Sigma_t : (x, p) \longmapsto (x + S_t p, \hspace{0.27em} p) . \) | (7.13) |
Its trajectories are the characteristics of the transport part of
The martingale term \(\Upsilon \mathrm{d} W\) is the price of
adaptedness: the costate may not anticipate the noise. For the field
\(\partial_x H = 0\), so the costate is a martingale, \(p_t
=\mathbb{E}_t [- \mathrm{D} V_T (X_T)]\), and since the value function
is the effective potential (Theorem 7.5), \(p_t = -
\mathrm{D} V_t (X_t)\). The noise adds the Itô term to the
Hamilton–Jacobi equation, which becomes the Polchinski equation
In the notation of Theorem 7.5 the controlled field is
\(\mathrm{d} X = \dot{Q}_t^{1 / 2} (u \hspace{0.17em} \mathrm{d} t +
\mathrm{d}
W)\) and the optimal control is \(u_t = \dot{Q}_t^{1 / 2}
p_t\) (Exercise 7.3). Since \(p_t\) is the value \(F_t\) of
the force, the FBSDE
the field \(\Phi\) is the state, and the force \(F\) is the costate.
Stochastic localisation was introduced by Eldan [Eld13] to study measures in high dimension (see [Eld23] for a survey). The idea is to write a measure as a mixture of simpler ones, through a measure-valued martingale driven by noise. Proposition 7.2 says that the Polchinski process does exactly this for \(\nu_T\). What Eldan's construction adds to the picture of Section 7.1 is a statistical reading:
the Polchinski process is a noisy observation of its own terminal value, and its drift is what an optimal filter learns from this observation.
| \(\displaystyle \Phi_t = J_t \Phi_T + \zeta_t, \quad \zeta_t \sim N (0, Q_t (1 - J_t)), \quad \text{independent of } \Phi_T . \) | (7.14) |
Read
| \(\displaystyle \mathrm{d} \Phi_t = \dot{Q}_t S_t^{- 1} (\Phi_T - \Phi_t) \hspace{0.17em} \mathrm{d} t + \dot{Q}_t^{1 / 2} \hspace{0.17em} \mathrm{d} B_t,\) | (7.15) |
with \(B\) a Brownian motion independent of \(\Phi_T\), in the filtration enlarged by \(\sigma (\Phi_T)\): at each resolution the field is pulled towards the hidden terminal field, and the pull is seen through noise. The filtering problem is to estimate \(\Phi_T\) from \(\mathcal{F}_t = \sigma (\Phi_s : s \leqslant t)\), the filtration of the Polchinski process itself. Let \(\psi_t =\mathbb{E}_t [\Phi_T]\), \(\text{Cov}_t = \text{Cov} (\Phi_T |\mathcal{F}_t)\), and let
be the regulator.
Proposition
The conditional law of \(\Phi_T\) given \(\mathcal{F}_t\) is the Bayesian posterior
| \(\displaystyle \mu_t^{\Phi_t} (\mathrm{d} y) \propto \mathrm{e}^{\langle S_t^{- 1} \Phi_t, y \rangle - \frac{1}{2} \langle y, \mathcal{R}_t y \rangle} \nu_T (\mathrm{d} y) .\) | (7.16) |
It depends on the path only through \(\Phi_t\), a sufficient statistic, and \(\mathcal{R}_t\) is the precision gained on \(\Phi_T\).
The Brownian motion \(W\) of the FBSDE
and the force is the posterior mean of the pull in
So
Every observable \(O_t =\mathbb{E}_t [G (\Phi_T)]\) solves the filter equation
in particular
Proof. (a) By Proposition 7.2 the
conditional law is \(\mu_t^{\Phi_t}\), the tilt of \(\mu^{S_t} (\cdot -
\Phi_t)\) by \(\mathrm{e}^{- V_T}\). The ratio of the Gaussian densities
of \(\mu^{S_t} (\cdot - x)\) and \(\mu^{Q_T}\) at \(y\) is
\(\mathrm{e}^{\langle S_t^{- 1} x, y \rangle - \frac{1}{2} \langle
y,
\mathcal{R}_t y \rangle}\) up to a function of \(x\); equivalently,
apply Bayes' formula to the likelihood of
So the Polchinski process is a filter. The interacting measure is the prior on a hidden field; at resolution \(t\) one has observed the coarse field \(\Phi_t\), and \(\mu_t^{\Phi_t}\) is what is known about the fine one. The forecast \(\psi_t\) is the posterior mean of the hidden field, and \(\dot{Q}_t F_t\) is the posterior mean of its pull on the observed one. For the Gaussian prior \(\mu^{Q_T}\) the increments are independent, so the posterior mean is \(\Phi_t\) itself and \(F = 0\): \(\Phi_t\) is the estimate that ignores the interaction and \(\psi_t\) the one that includes it. The effective potential is a likelihood ratio: by the proof of Theorem 7.3, \(Z_T^{- 1} \mathrm{e}^{- V_t (\Phi_t)}\) is the likelihood ratio of the observation up to resolution \(t\) under the interacting and under the Gaussian prior, and the Polchinski equation is the equation of its logarithm.
Proposition
with \(\hat{W}\) a Brownian motion independent of \(\Phi_T\), and
its solution is
Proof. Under \(\mathbb{P}_0\), \(X\) is a
centred Gaussian process with independent increments, so its reversal is
a Gaussian Markov process: for \(t < u\), the law of \(X_t\) given
\((X_r)_{r \geqslant u}\) is \(N (Q_t Q_u^{- 1} X_u, Q_t - Q_t Q_u^{- 1}
Q_t)\), and letting \(u \downarrow t\) gives the drift and the diffusion
of
the force is the score of \(\nu_t\) relative to that of the Gaussian reference \(\mu^{Q_t}\), as \(\nu_t \propto \mathrm{e}^{- V_t} \mu^{Q_t}\) requires. The forecast is the optimal denoiser, and Tweedie's formula
is again \(\psi_t = \Phi_t + S_t F_t\). This is the structure of score-based generative models (diffusion models), with \(\nu_T\) as the data distribution, the blurring as the noising process and the Polchinski process as the generating dynamics.
Remark
| \(\displaystyle j_t =\mathcal{R}_t \Phi_T + N_t, \quad N_t = S_t^{- 1} \zeta_t, \quad \mathbb{E} [N_s \otimes N_t] =\mathcal{R}_{s \wedge t}, \quad N \text{ independent of } \Phi_T . \) | (7.18) |
In this coordinate
and
up to a function of \(t\). Then \(\psi_t = \mathrm{D} \mathcal{K}_t (j_t)\), \(\text{Cov}_t = \mathrm{D}^2 \mathcal{K}_t (j_t)\), \(\hspace{0.17em} \mathrm{d} j_t = \dot{\mathcal{R}}_t \psi_t \hspace{0.17em} \mathrm{d} t + \dot{\mathcal{R}}_t^{1 / 2} \hspace{0.17em} \mathrm{d} W_t\) with the same innovation \(W\), and
the Polchinski equation in the variable \(j\) [BBD24] (\(\partial_t \mathcal{K}= - \frac{1}{2} \mathbb{E} \langle y, \dot{\mathcal{R}} y \rangle\) and \(\text{Tr} (\dot{\mathcal{R}} \mathrm{D}^2 \mathcal{K}) =\mathbb{E} \langle y, \dot{\mathcal{R}} y \rangle - \langle \psi, \dot{\mathcal{R}} \psi \rangle\), expectations under the posterior). The basic form of Eldan's scheme is the profile \(S_t = (Q_T^{- 1} + t)^{- 1}\), \(t \in [0, \infty)\) (the terminal resolution is then \(t = \infty\), and \(Q_T\) is the cutoff covariance), where \(\mathcal{R}_t = t\) and \(j_t = t \Phi_T + N_t\) with \(N\) a Brownian motion; Eldan's original construction [Eld13] uses an adapted control matrix. This is the profile of Lectures 5–6.
The three constructions give one process. Renormalisation produces it as the field at resolution \(t\) with its effective drift (Theorem 7.3), control as the optimal state (7.11), and filtering as the observation written in its own filtration (Proposition 7.6). Each of them has a name for each object:
|
Renormalisation |
Control |
Filtering |
\(t\) |
resolved covariance \(Q_t\) |
time of the problem |
information gained \(\mathcal{R}_t\) |
\(\Phi_t\) |
field at resolution \(t\) |
state |
observation; posterior mean for the Gaussian prior |
\(F_t\) |
effective force |
costate |
posterior mean of the terminal force |
\(W\) |
fresh fluctuation of the shell |
noise of the controlled field |
innovation |
\(S_t\) |
unresolved covariance |
free motion from \(t\) to \(T\) |
posterior covariance for the Gaussian prior |
\(\psi_t = \Phi_t + S_t F_t\) |
mean of the conditional law \(\mu_t^{\Phi_t}\) |
terminal state predicted by free motion |
posterior mean |
\(\text{Cov}_t\) |
covariance of \(\mu_t^{\Phi_t}\) |
\(S_t - S_t \mathrm{D}^2 V_t S_t\) |
posterior covariance |
\(V_t\) |
effective potential |
value function |
minus the log-likelihood ratio of the observation, up to \(\log Z_T\) |
In the last column, \(\Phi_t\) is the estimate of the terminal field that ignores the interaction, and \(\psi_t\) is the estimate that includes it. Their difference is \(S_t F_t\): the force is what the interaction adds to the estimate, in units of the free propagator \(S_t\). The conditional covariance \(\text{Cov}_t\) replaces \(S_t\) as the propagator. Forces, propagators and covariances are the common language of the three views, and the next section writes the system in it. Only the last row of the table, and the formula for \(\text{Cov}_t\) in the control column, involve a potential.
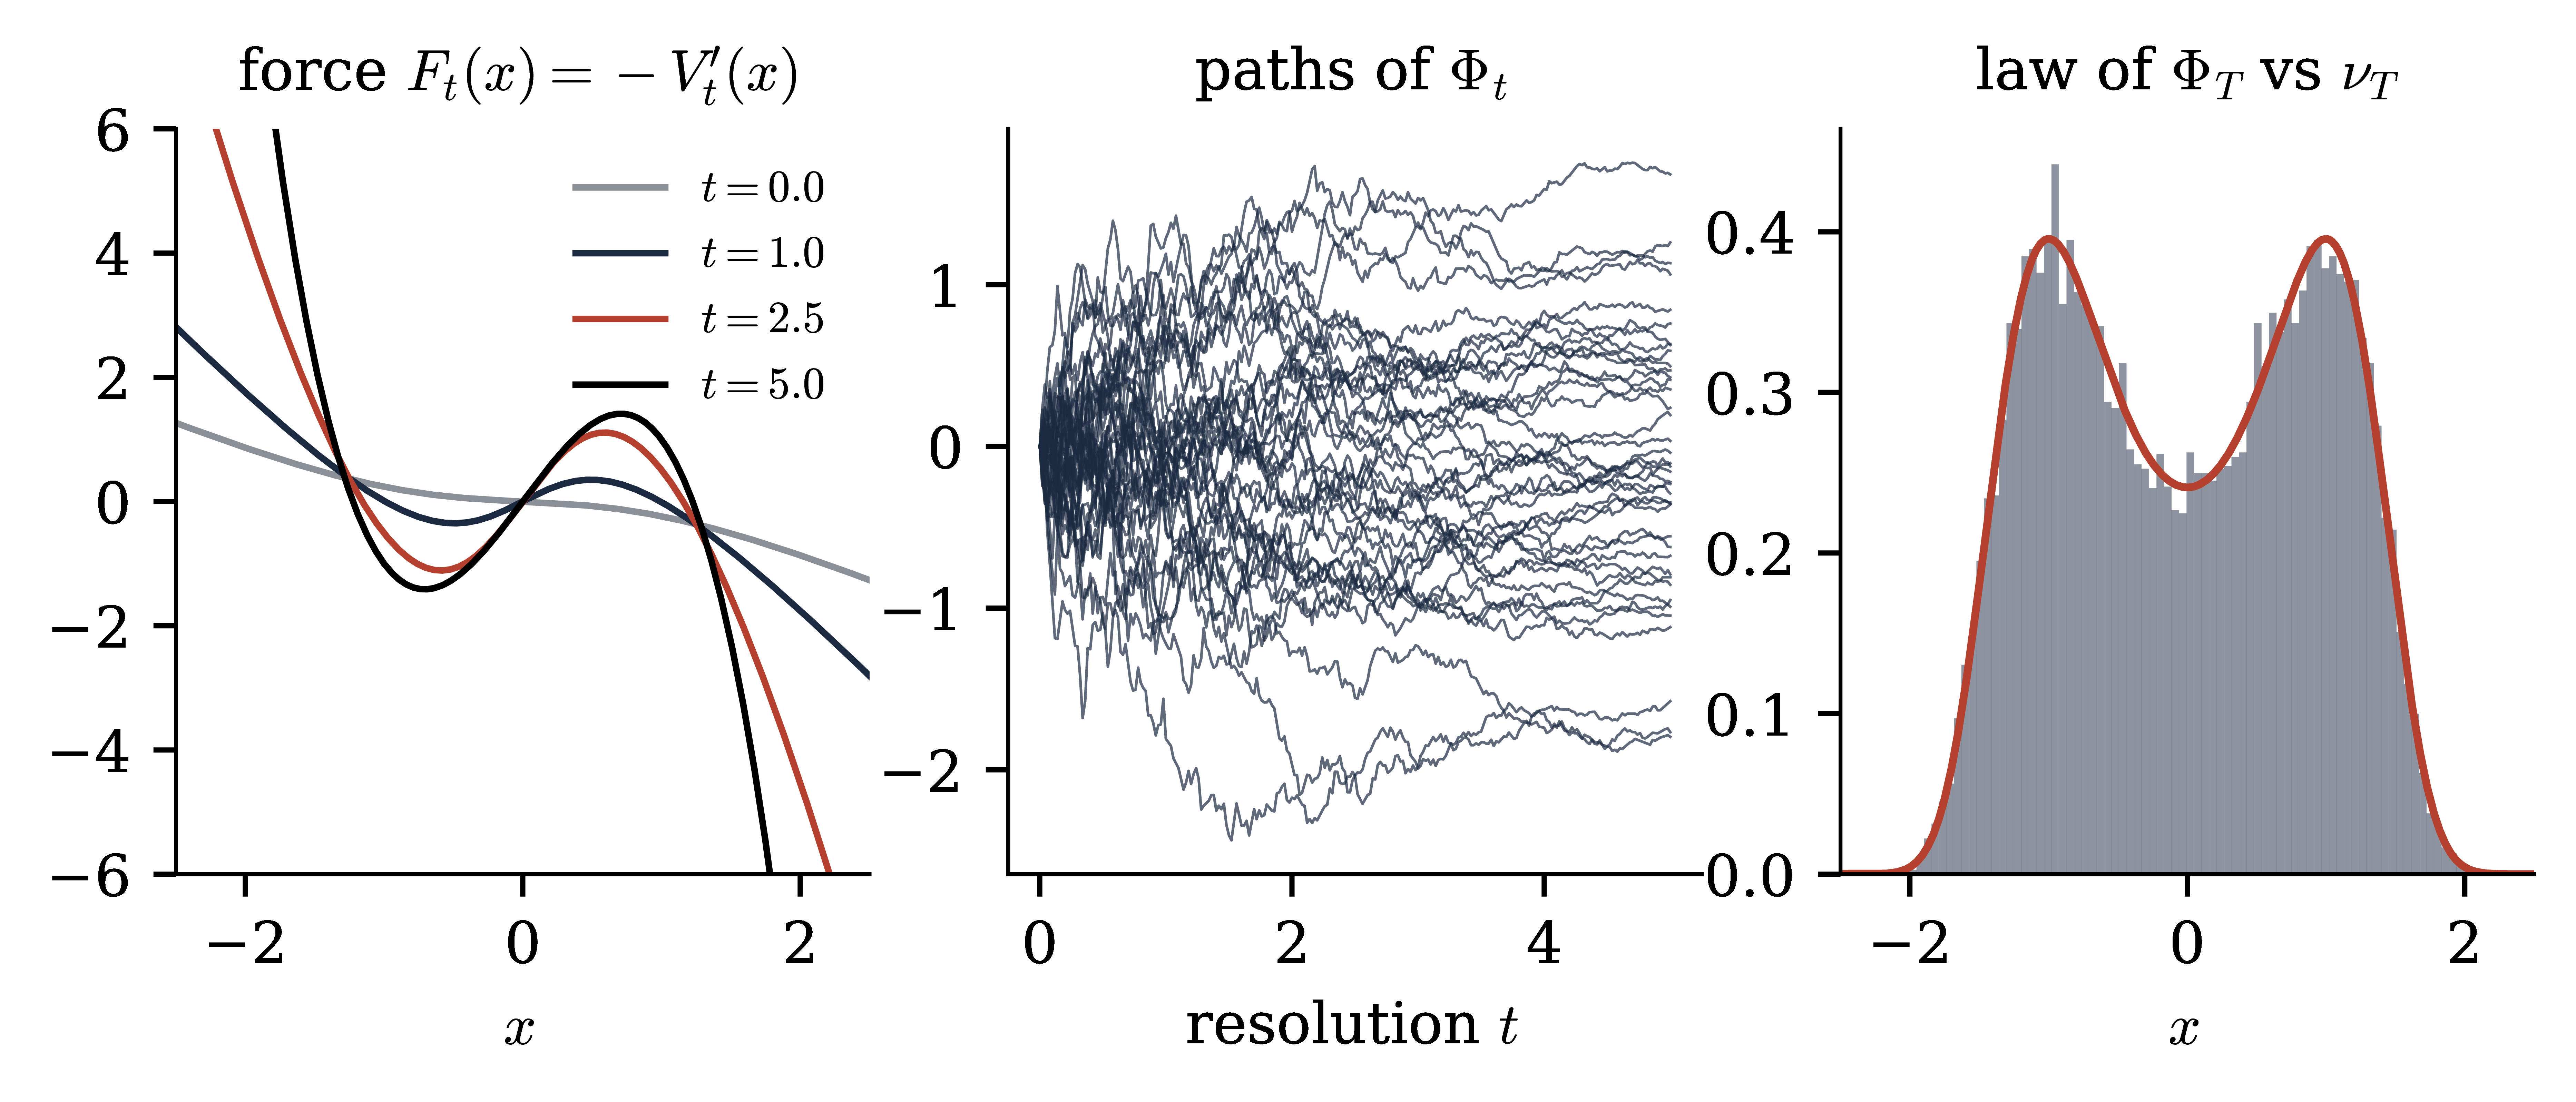
|
Figure 7.2. A zero-dimensional Polchinski
process (Exercise 7.2): \(Q_t = 1 - \mathrm{e}^{-
t}\), \(T = 5\), \(V_T (x) = \frac{1}{2} x^4 - \frac{3}{2}
x^2\). Left: the effective force \(F_t = - V_t'\) is almost
linear at low resolution and develops the double-well structure
as \(t \to T\). Centre: paths of the FBSDE |
Exercise
Exercise
Exercise
Exercise
Exercise
which diverges linearly in \(T\). Relate this to the \(k
= 4\) term of
The three views agree on the forward–backward system (7.7), which from now on is the primary object, with a martingale force \(F_t = F_t (\Phi_t)\), \(\hspace{0.17em} \mathrm{d} F_t = \Upsilon_t \hspace{0.17em} \mathrm{d} W_t\). We look for the coordinates in which it is simplest. They are suggested by the table above: the posterior mean \(\psi\), which we call the forecast, and the force. They remove the predictable part of the forward dynamics, and they integrate exactly the bilinear (tree) part of the force flow.
Sections 8.1–8.4 tell this story in terms of forces, propagators and covariances. The potential enters only through the terminal force and, for a gradient force, through the identification of the response with the conditional covariance; the system in force coordinates makes sense for a force that is not a gradient. Sections 8.5–8.7 tell it again in terms of potentials: the value function generates the canonical transformation to force coordinates, the Legendre transform connects it to the filter, and the equation for the force is the Wetterich equation for the effective average action [Wet93, BTW02].
Differentiating
| \(\displaystyle \partial_t F_t = - \mathrm{D} F_t [\dot{Q}_t F_t] - \tfrac{1}{2} \text{Tr} (\dot{Q}_t \mathrm{D}^2 F_t), \qquad F_T = - \mathrm{D} V_T,\) | (8.1) |
an infinite-dimensional, backward, viscous Burgers equation.
The Cole–Hopf transform \(F = \mathrm{D} \log u\) linearises it,
which is the statement that \(u = \mathrm{e}^{- V}\) solves a heat
equation. Two remarks on
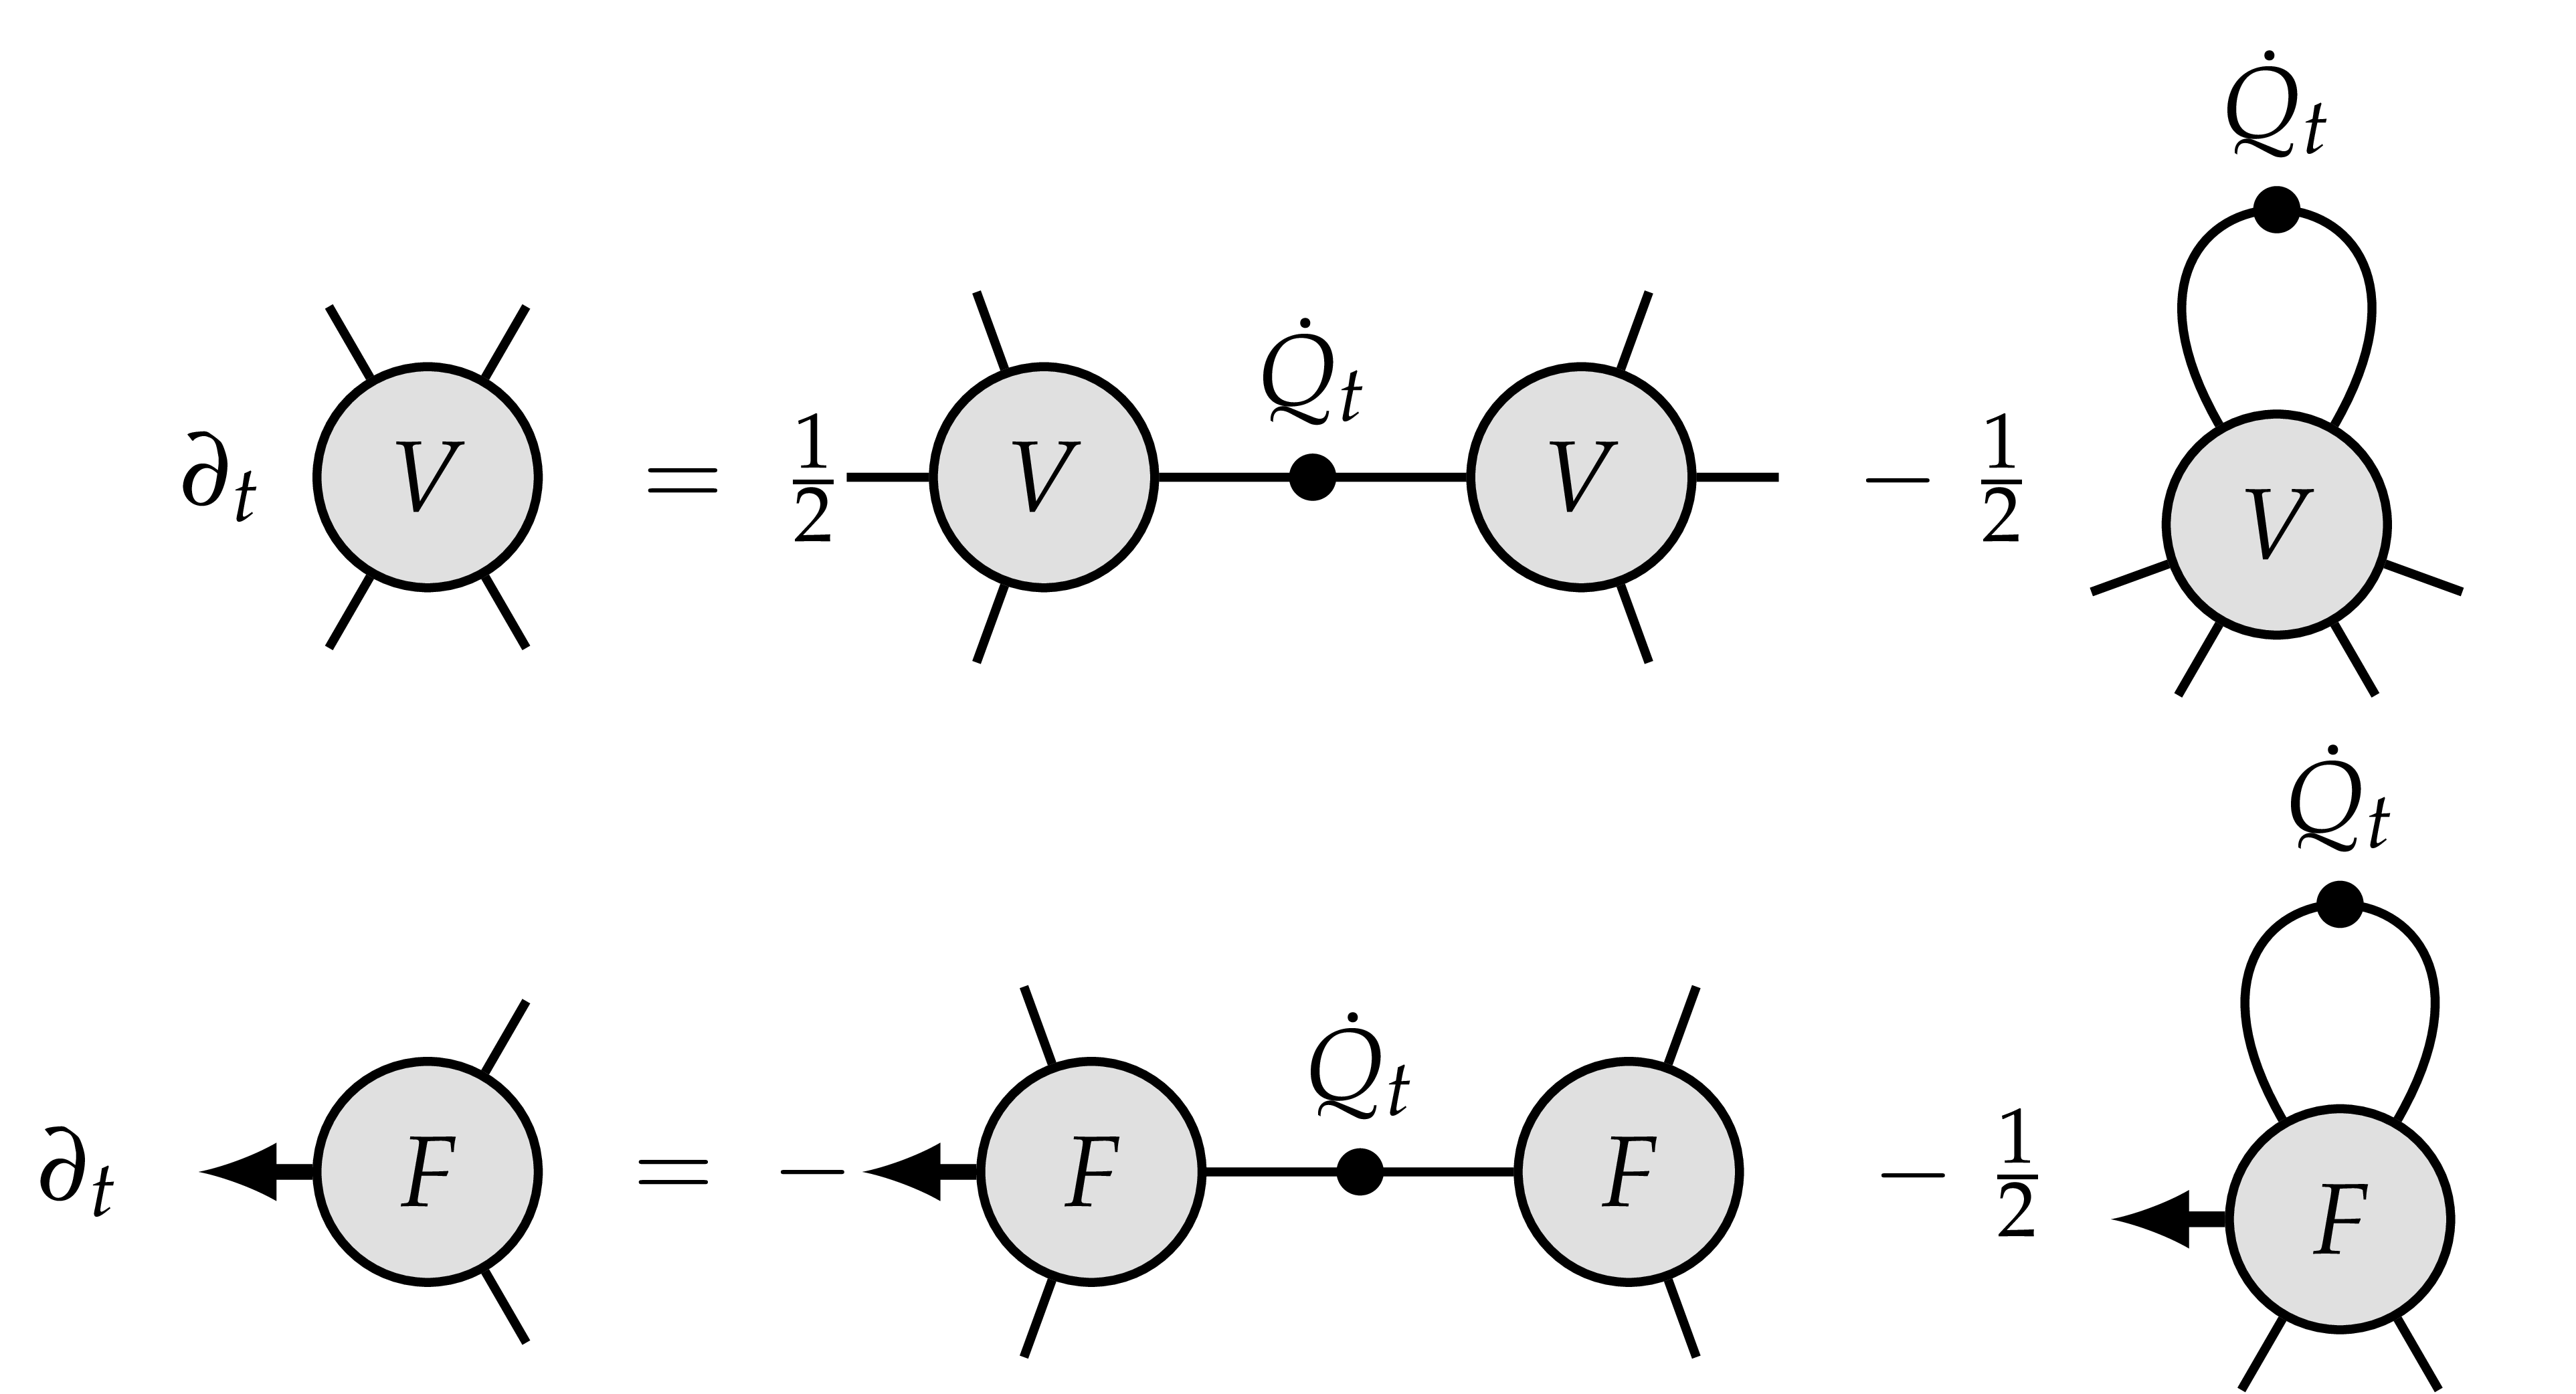
|
Figure 8.1. The Polchinski equation
|
it uses only the force, which is a local quantity (intensive), while \(V_t\) is extensive, of order of the volume. This matters in infinite volume (Section 9.4);
the Burgers flows for different covariances commute, and the curvature vanishes, when \(\mathrm{D} F_t\) is symmetric, i.e. when \(F_t\) is a gradient [BCG26]. For a non-gradient force, as for the general Wilson–Itô diffusions of [BCG26], the flows do not commute.
The function \(F_t (\cdot)\) with \(F_t = F_t (\Phi_t)\) is the
decoupling field of the FBSDE, and the Burgers equation
The drift \(\dot{Q}_t F_t\) of the state is predictable, and the costate
is a martingale. Hence the drift that remains to be accumulated on \([t,
T]\) is predicted, at resolution \(t\), by transporting the current
state with the current costate along the free flow
Proposition
| \(\displaystyle \psi_t := \mathbb{E}_t [\Phi_T] = \Phi_t + S_t F_t,\) | (8.2) |
i.e. \((\psi_t, F_t) = \Sigma_t (\Phi_t, F_t)\). It is a martingale, with
Proof. The identity is in the proof of Proposition 7.6(b), and uses no commutativity. For the differential, the drift \(\dot{Q}_t F_t\) of \(\Phi\) cancels against \(\dot{S}_t F_t\), and \(S_t \hspace{0.17em} \mathrm{d} F_t = S_t \Upsilon_t \hspace{0.17em} \mathrm{d} W_t\).\(\Box\)
So \(\psi\) is a closed observable, the field observable of [BCG26]. The field splits as
| \(\displaystyle \Phi_t = \psi_t - S_t F_t :\) | (8.4) |
a martingale, minus the drift still expected on the unresolved scales,
which vanishes at \(t = T\). The noise of \(\psi\) in
Assume that the map
is invertible, and write its inverse as
| \(\displaystyle x = \psi + S_t \mathcal{F}_t (\psi), \qquad \mathcal{F}_t (\psi) := - F_t (x),\) | (8.5) |
so that \(F_t = -\mathcal{F}_t (\psi_t)\): the costate is now a function of the forecast. Introduce the response, and recall the regulator of the filter:
Differentiating the two maps \(x \leftrightarrow \psi\) gives
Theorem
with \(\psi_0 = S_0 F_0 =\mathbb{E} [\Phi_T]\) and \(\psi_T = \Phi_T\). The forward equation has no drift, and its covariance is
The decoupling field \(\mathcal{F}\) solves the pure diffusion equation
Proof. The forward equation is
The backward equation is \(F_t =\mathbb{E}_t [F_T]\) with \(\psi_T =
\Phi_T\). Since \(\mathcal{F}_t (\psi_t)\) is a martingale and \(\psi\)
has no drift, the drift in Itô's formula for \(\mathcal{F}_t
(\psi_t)\) is the left-hand side of
Compare
Along the characteristics \(x = y + sg' (y)\) the velocity is constant, \(u (s, y + sg' (y)) = g' (y)\): in the Lagrangian label \(y\) the transport term disappears, and nothing moves. As long as the characteristics do not cross, i.e. \(1 + sg'' > 0\), the map \(y \mapsto x\) is invertible, and \(u = \partial_x G\) with the potential given by the Lax–Oleinik formula (or Hopf–Lax formula)
whose minimiser \(y (s, x)\) is the Lagrangian label of the point \(x\). After the characteristics cross, the formula still selects one label, the entropy solution, and \(u\) has shocks. The viscous equation \(\partial_s u + u \partial_x u = \varepsilon \partial_x^2 u\) is linearised by the Cole–Hopf transform,
and \(G^{\varepsilon} \to G\) as \(\varepsilon \to 0\) by Laplace's method.
The dictionary with this section is: the unresolved covariance \(S_t\)
is the time \(s\), the field \(x\) is the Eulerian point, the forecast
\(\psi\) is the Lagrangian label \(y\), \(- F_t = \mathrm{D} V_t\) is
the velocity \(u\) (and \(V_t\) is \(G\)), and \(V_T\) is the datum
\(g\). The shear
Theorem 8.2 is the Lagrangian description of the
viscous problem. With noise the label is no longer a function
of the Eulerian point: it is its posterior mean, the mean \(\psi\) of
\(y\) under the Cole–Hopf measure \(\propto \mathrm{e}^{- g (y) -
(x - y)^2 / 2 s}\), which is \(\mu_t^x\). In this label the velocity is
no longer constant but a martingale, and its evolution
For the Polchinski process the response has a direct meaning.
Proposition
In particular \(H_t > 0\) is symmetric, \(\mathbb{1} + S_t \mathrm{D} F_t = \text{Cov}_t S_t^{- 1}\) is always invertible, and \(H_t \leqslant S_t\) when \(V_T\) is convex.
Proof. By
So the forecast and the response are the first two conditional moments of the stochastic localisation \(\mu_t^{\Phi_t}\) of Proposition 7.2: \((\psi_t, \text{Cov}_t) = (\mathbb{E}[\Phi_T \hspace{0.17em} | \hspace{0.17em} \Phi_t], \text{Cov} (\Phi_T \hspace{0.17em} | \hspace{0.17em} \Phi_t))\) (Figure 8.2). They are tied by Itô's formula: since \(\mathbb{E}_t [\Phi_T \otimes \Phi_T] = \psi_t \otimes \psi_t + \text{Cov}_t\) is a martingale,
Conditional variance is resolved at the rate \(\text{Cov}_t \dot{\mathcal{R}}_t \text{Cov}_t\), which for the Gaussian reference is \(S_t \dot{\mathcal{R}}_t S_t = \dot{Q}_t\).
The lower bound follows from \(\mathbb{E}_{\mu} [(y - m) \otimes \mathrm{D} \mathcal{U}(y)] = 1\) (integration by parts) and the Cauchy–Schwarz inequality, with the Fisher information \(\mathbb{E}_{\mu} [\mathrm{D} \mathcal{U} \otimes \mathrm{D} \mathcal{U}] =\mathbb{E}_{\mu} \mathrm{D}^2 \mathcal{U}\) (Exercise 8.9). The two bounds coincide when \(V_T\) is quadratic, and their gap is a Jensen gap for the inverse. Through Proposition 8.3 they are two-sided bounds on the Hessian of the effective potential, i.e. on the response \(H_t\), which is the propagator of the Wetterich equation below. Some consequences:
If \(V_T\) is convex, then \(\operatorname{Cov}_t \leqslant S_t\): the interaction can only reduce the conditional variance. Equivalently \(\mathrm{D}^2 V_t \geqslant 0\): convexity is preserved along the Polchinski flow (as also follows from the Prékopa–Leindler inequality).
If \(\mathrm{D}^2 V_T \geqslant \kappa\) with \(\kappa > 0\), then \(\operatorname{Cov}_t \leqslant (S_t^{- 1} + \kappa)^{- 1}\) uniformly in the conditioning: a uniform mass in the interaction is a uniform mass in every conditional law.
For \(\Phi^4_3\) convexity is already lost through the Wick
ordering: \(H_4 (\varphi ; c_T) = \varphi^4 - 6 c_T \varphi^2 + 3
c_T^2\), so
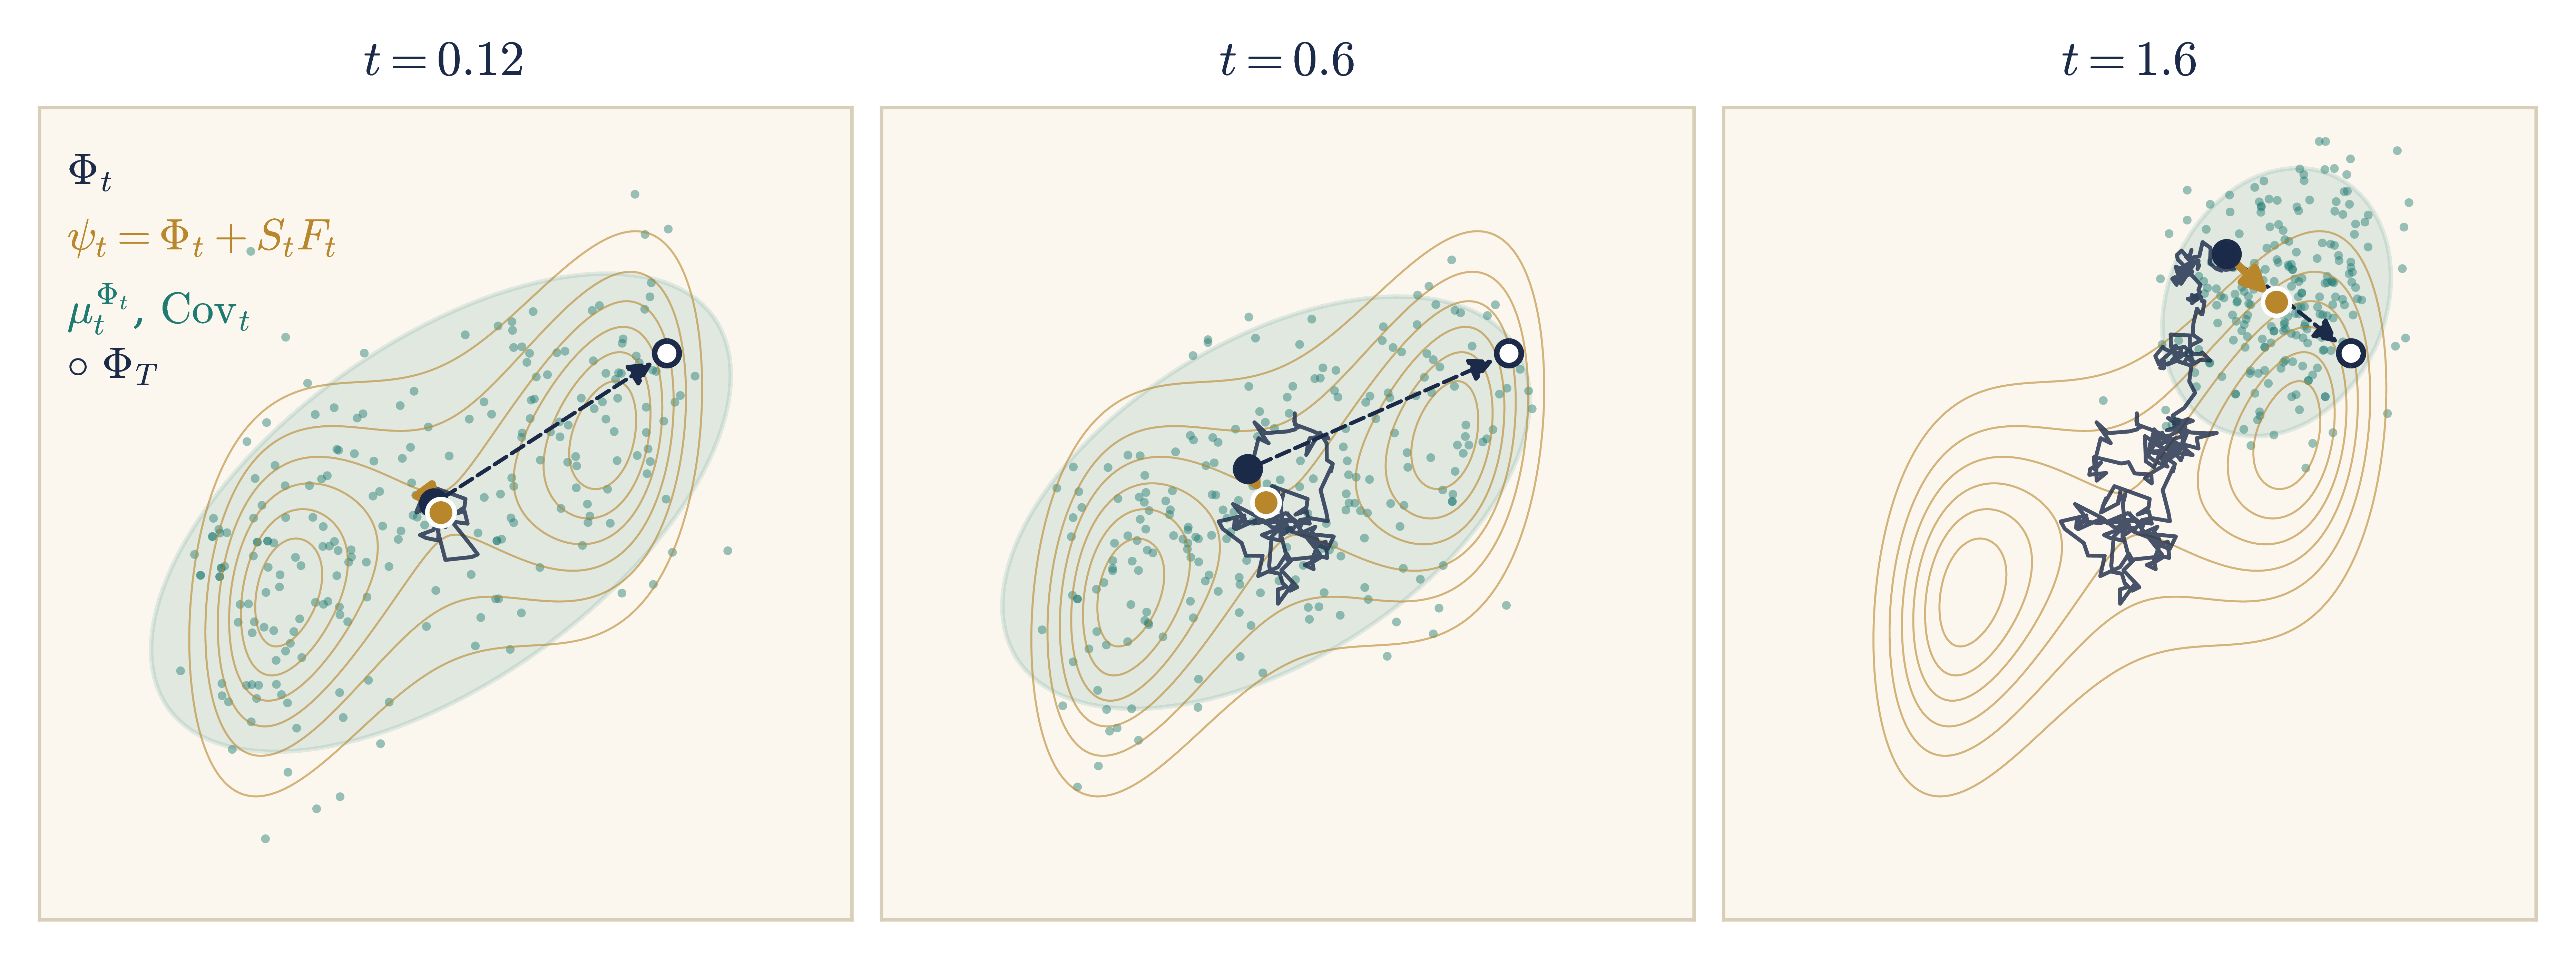
|
Figure 8.2. Stochastic localisation for a
two-component field: \(Q_t = (1 - \mathrm{e}^{- t})
\mathbb{1}\), \(T = 4\), \(V_T\) a tilted double well, and the
contours show the density of \(\nu_T\). One path of |
We now use that the force is a gradient, \(F_t = - \mathrm{D} V_t\), whose graph is a Lagrangian submanifold, and that \(V_t\) is the value function of Theorem 7.5. In Hamilton–Jacobi theory a value function is more than a cost: it generates a canonical transformation. A complete family of solutions of the Hamilton–Jacobi equation generates the transformation that trivialises the dynamics. Force coordinates are this transformation.
| \(\displaystyle \mathcal{A}_t (x, \psi) = \frac{1}{2} \langle \psi - x, S_t^{- 1} (\psi - x) \rangle . \) | (8.10) |
The relation \(\psi = x + S_t p\) is the shear (7.13). Since \(\mathrm{D}_x \mathcal{A}_t = - p\) and \(\mathrm{D}_{\psi} \mathcal{A}_t = p\), at fixed \(t\)
so \(\mathcal{A}_t\) is the generating function of the canonical transformation \(\Sigma_t\). Moreover
for every \(\psi\) it solves the noiseless Polchinski equation, so it is a complete integral of that equation, with parameter \(\psi\). Jacobi's theorem then says that in the new coordinates the Hamiltonian \(H_{\ast}\) vanishes: \(\psi\) and \(p\) are constants of motion.
This is what force coordinates are:
\((\psi_t, F_t)\) are the Jacobi coordinates of the free Hamiltonian of the field.
The noise does not destroy this: the constants of motion become martingales, \(\psi_t\) by Proposition 8.1 and \(F_t\) by Theorem 7.3. The only dynamics left is their quadratic variation.
| \(\displaystyle \mathcal{F}_t = \mathrm{D} \Gamma_t, \qquad H_t = (S_t^{- 1} + \mathrm{D}^2 \Gamma_t)^{- 1}, \qquad \Gamma_T = V_T .\) | (8.11) |
These two generating functions are related by the Moreau (infimal convolution) transform
| \(\displaystyle V_t (x) = \inf_{\psi} \left\{ \Gamma_t (\psi) + \tfrac{1}{2} \langle x - \psi, S_t^{- 1} (x - \psi) \rangle \right\},\) | (8.12) |
whose optimality conditions \(x = \psi + S_t \mathrm{D} \Gamma_t
(\psi)\), \(\mathrm{D} V_t (x) = \mathrm{D} \Gamma_t (\psi)\) are
At the minimiser, \(V_t (x) = \Gamma_t (\psi) +\mathcal{A}_t (x, \psi)\): the value function is the cost \(\Gamma_t\) attached to the forecast, plus the cost of reaching the forecast by free motion. This is the rule for transporting a generating function along a canonical transformation:
since \(\mathrm{D} \Gamma_t (\psi) = - F_t = - p\).
For \(\Gamma_t\) one only gets semiconvexity, \(S_t^{- 1} + \mathrm{D}^2
\Gamma_t =\operatorname{Cov}_t^{- 1} > 0\), i.e. \(\Gamma_t +
\frac{1}{2} \langle \cdot, S_t^{- 1} \cdot \rangle\) is strictly convex,
which is what
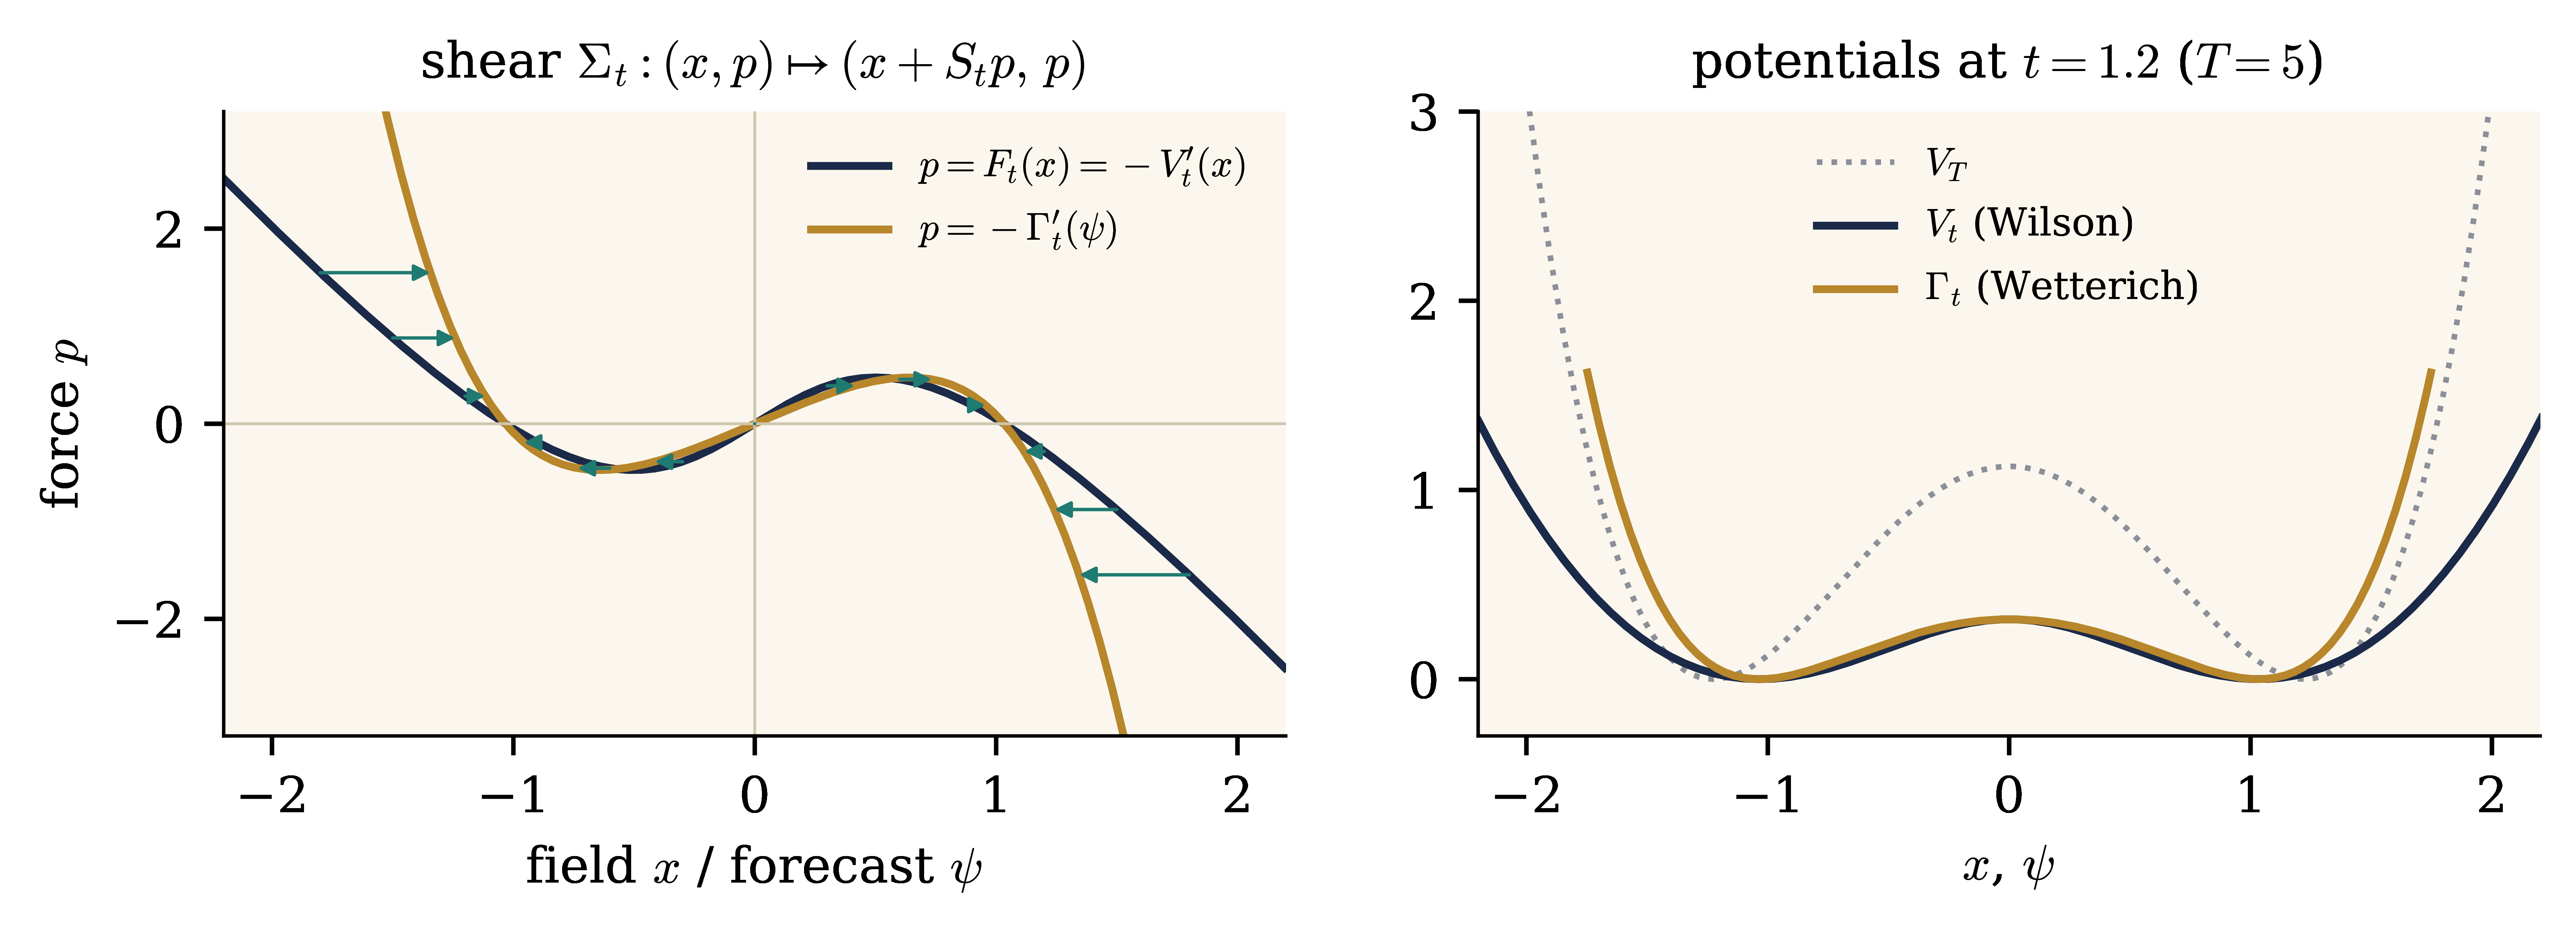
|
Figure 8.3. The zero-dimensional model of Figure 7.2 at \(t = 1.2\). Left: the shear \(\Sigma_t\) (teal arrows) maps the graph of the force \(F_t = - V_t'\) (navy) to a graph over the forecast \(\psi\) (gold), which is the graph of \(- \Gamma_t'\). Right: the bare potential \(V_T\), the effective potential \(V_t\) and \(\Gamma_t\), each shifted to have minimum \(0\). |
Theorem
| \(\displaystyle \partial_t \Gamma_t = \tfrac{1}{2} \text{Tr} [\dot{\mathcal{R}}_t ((S_t^{- 1} + \mathrm{D}^2 \Gamma_t)^{- 1} - S_t)], \qquad \Gamma_T = V_T .\) | (8.13) |
Equivalently, the effective average action \(\Gamma^{\text{EAA}}_t (\psi) := \Gamma_t (\psi) + \frac{1}{2} \langle \psi, Q_T^{- 1} \psi \rangle\) solves, up to a field-independent term,
| \(\displaystyle \partial_t \Gamma^{\text{EAA}}_t = \tfrac{1}{2} \text{Tr} [\dot{\mathcal{R}}_t (\mathrm{D}^2 \Gamma^{\text{EAA}}_t +\mathcal{R}_t)^{- 1}] .\) | (8.14) |
It interpolates between the bare action
(\(\mathcal{R}_T = \infty\)) and the 1PI effective action \(\Gamma^{\text{EAA}}_0\) of \(\nu_T\) (\(\mathcal{R}_0 = 0\)).
Proof. Integrate
Hence
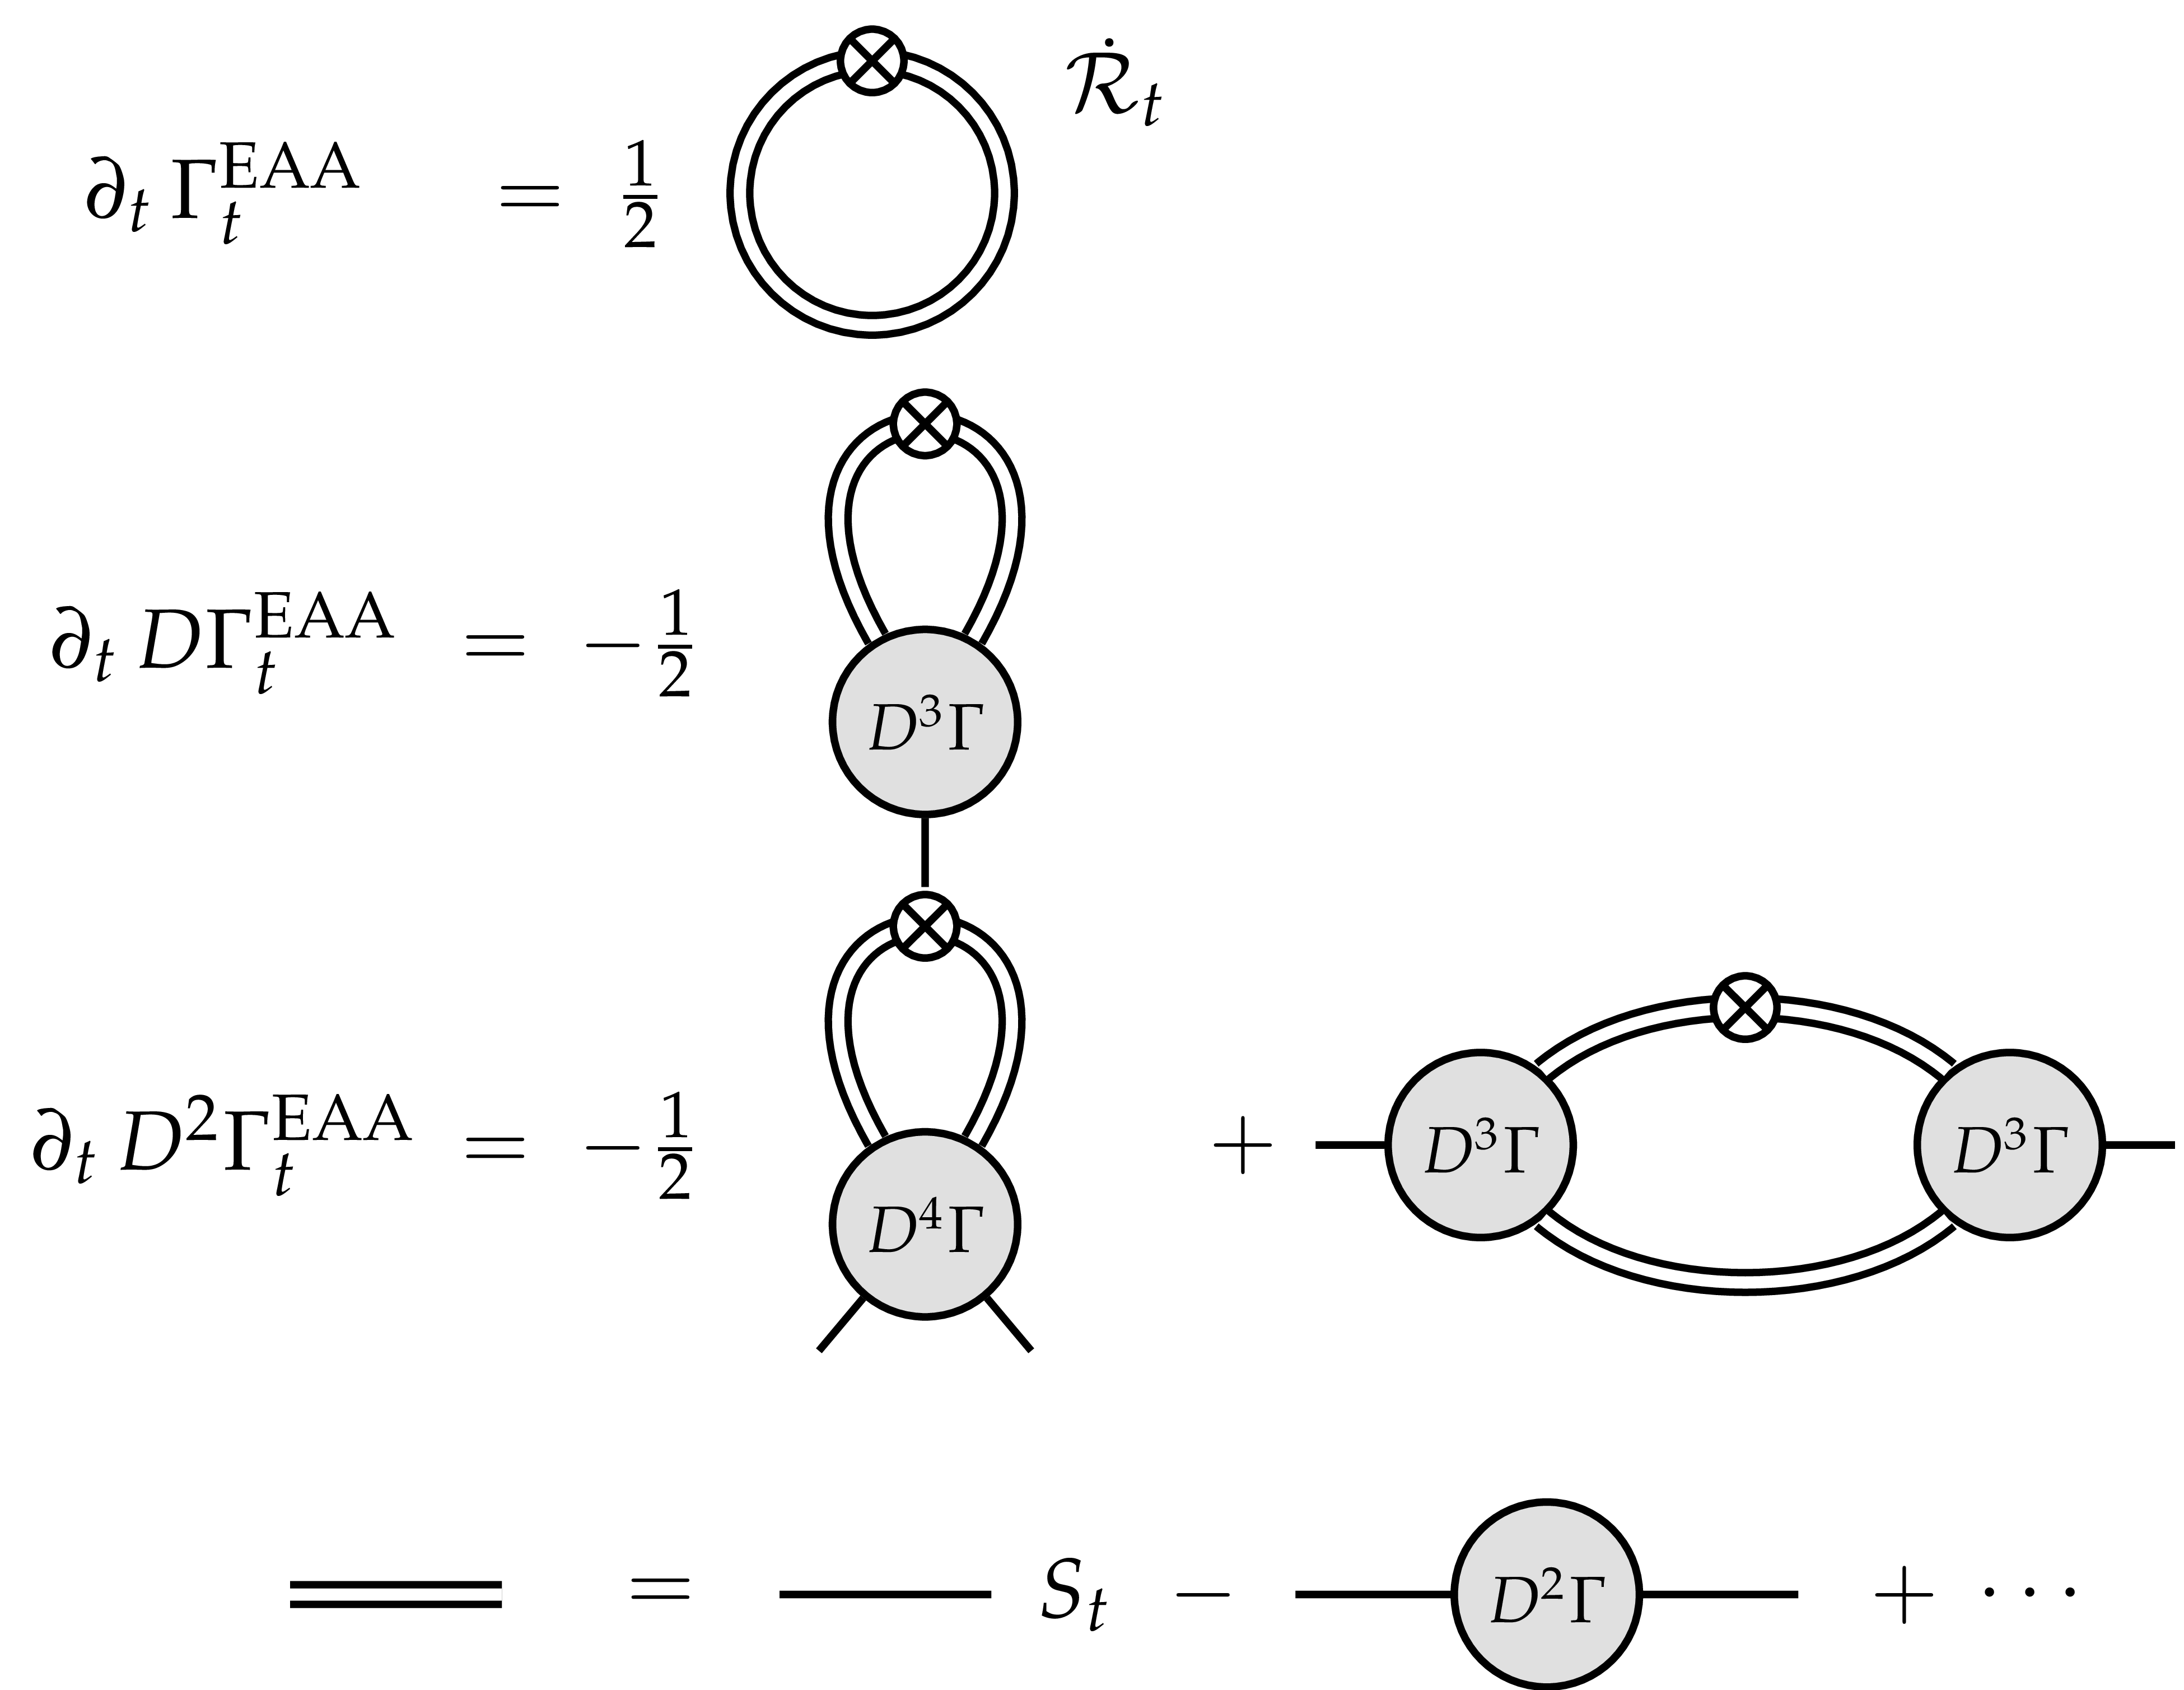
|
Figure 8.4. The Wetterich equation
|
Thus the Wetterich equation is the gradient-integrated form of the force
equation
Wetterich
FBSDE
field argument \(\psi\)
forecast \(\psi_t =\mathbb{E}_t [\Phi_T]\), the state
transported by \(\Sigma_t\)
\(\mathrm{D} \Gamma_t (\psi_t)\)
minus the costate, \(- F_t =\mathbb{E}_t [\mathrm{D}
V_T (\Phi_T)]\)
propagator \((\mathrm{D}^2 \Gamma^{\text{EAA}}_t
+\mathcal{R}_t)^{- 1}\)
conditional covariance \(\text{Cov}_t\)
regulator \(\mathcal{R}_t = S_t^{- 1} - Q_T^{-
1}\)
precision of the unresolved shell, minus that of the
prior
\(\partial_t \Gamma_t\)
\(\frac{1}{2} \text{Tr} [\dot{\mathcal{R}}_t
(\text{Cov}_t - S_t)]\)
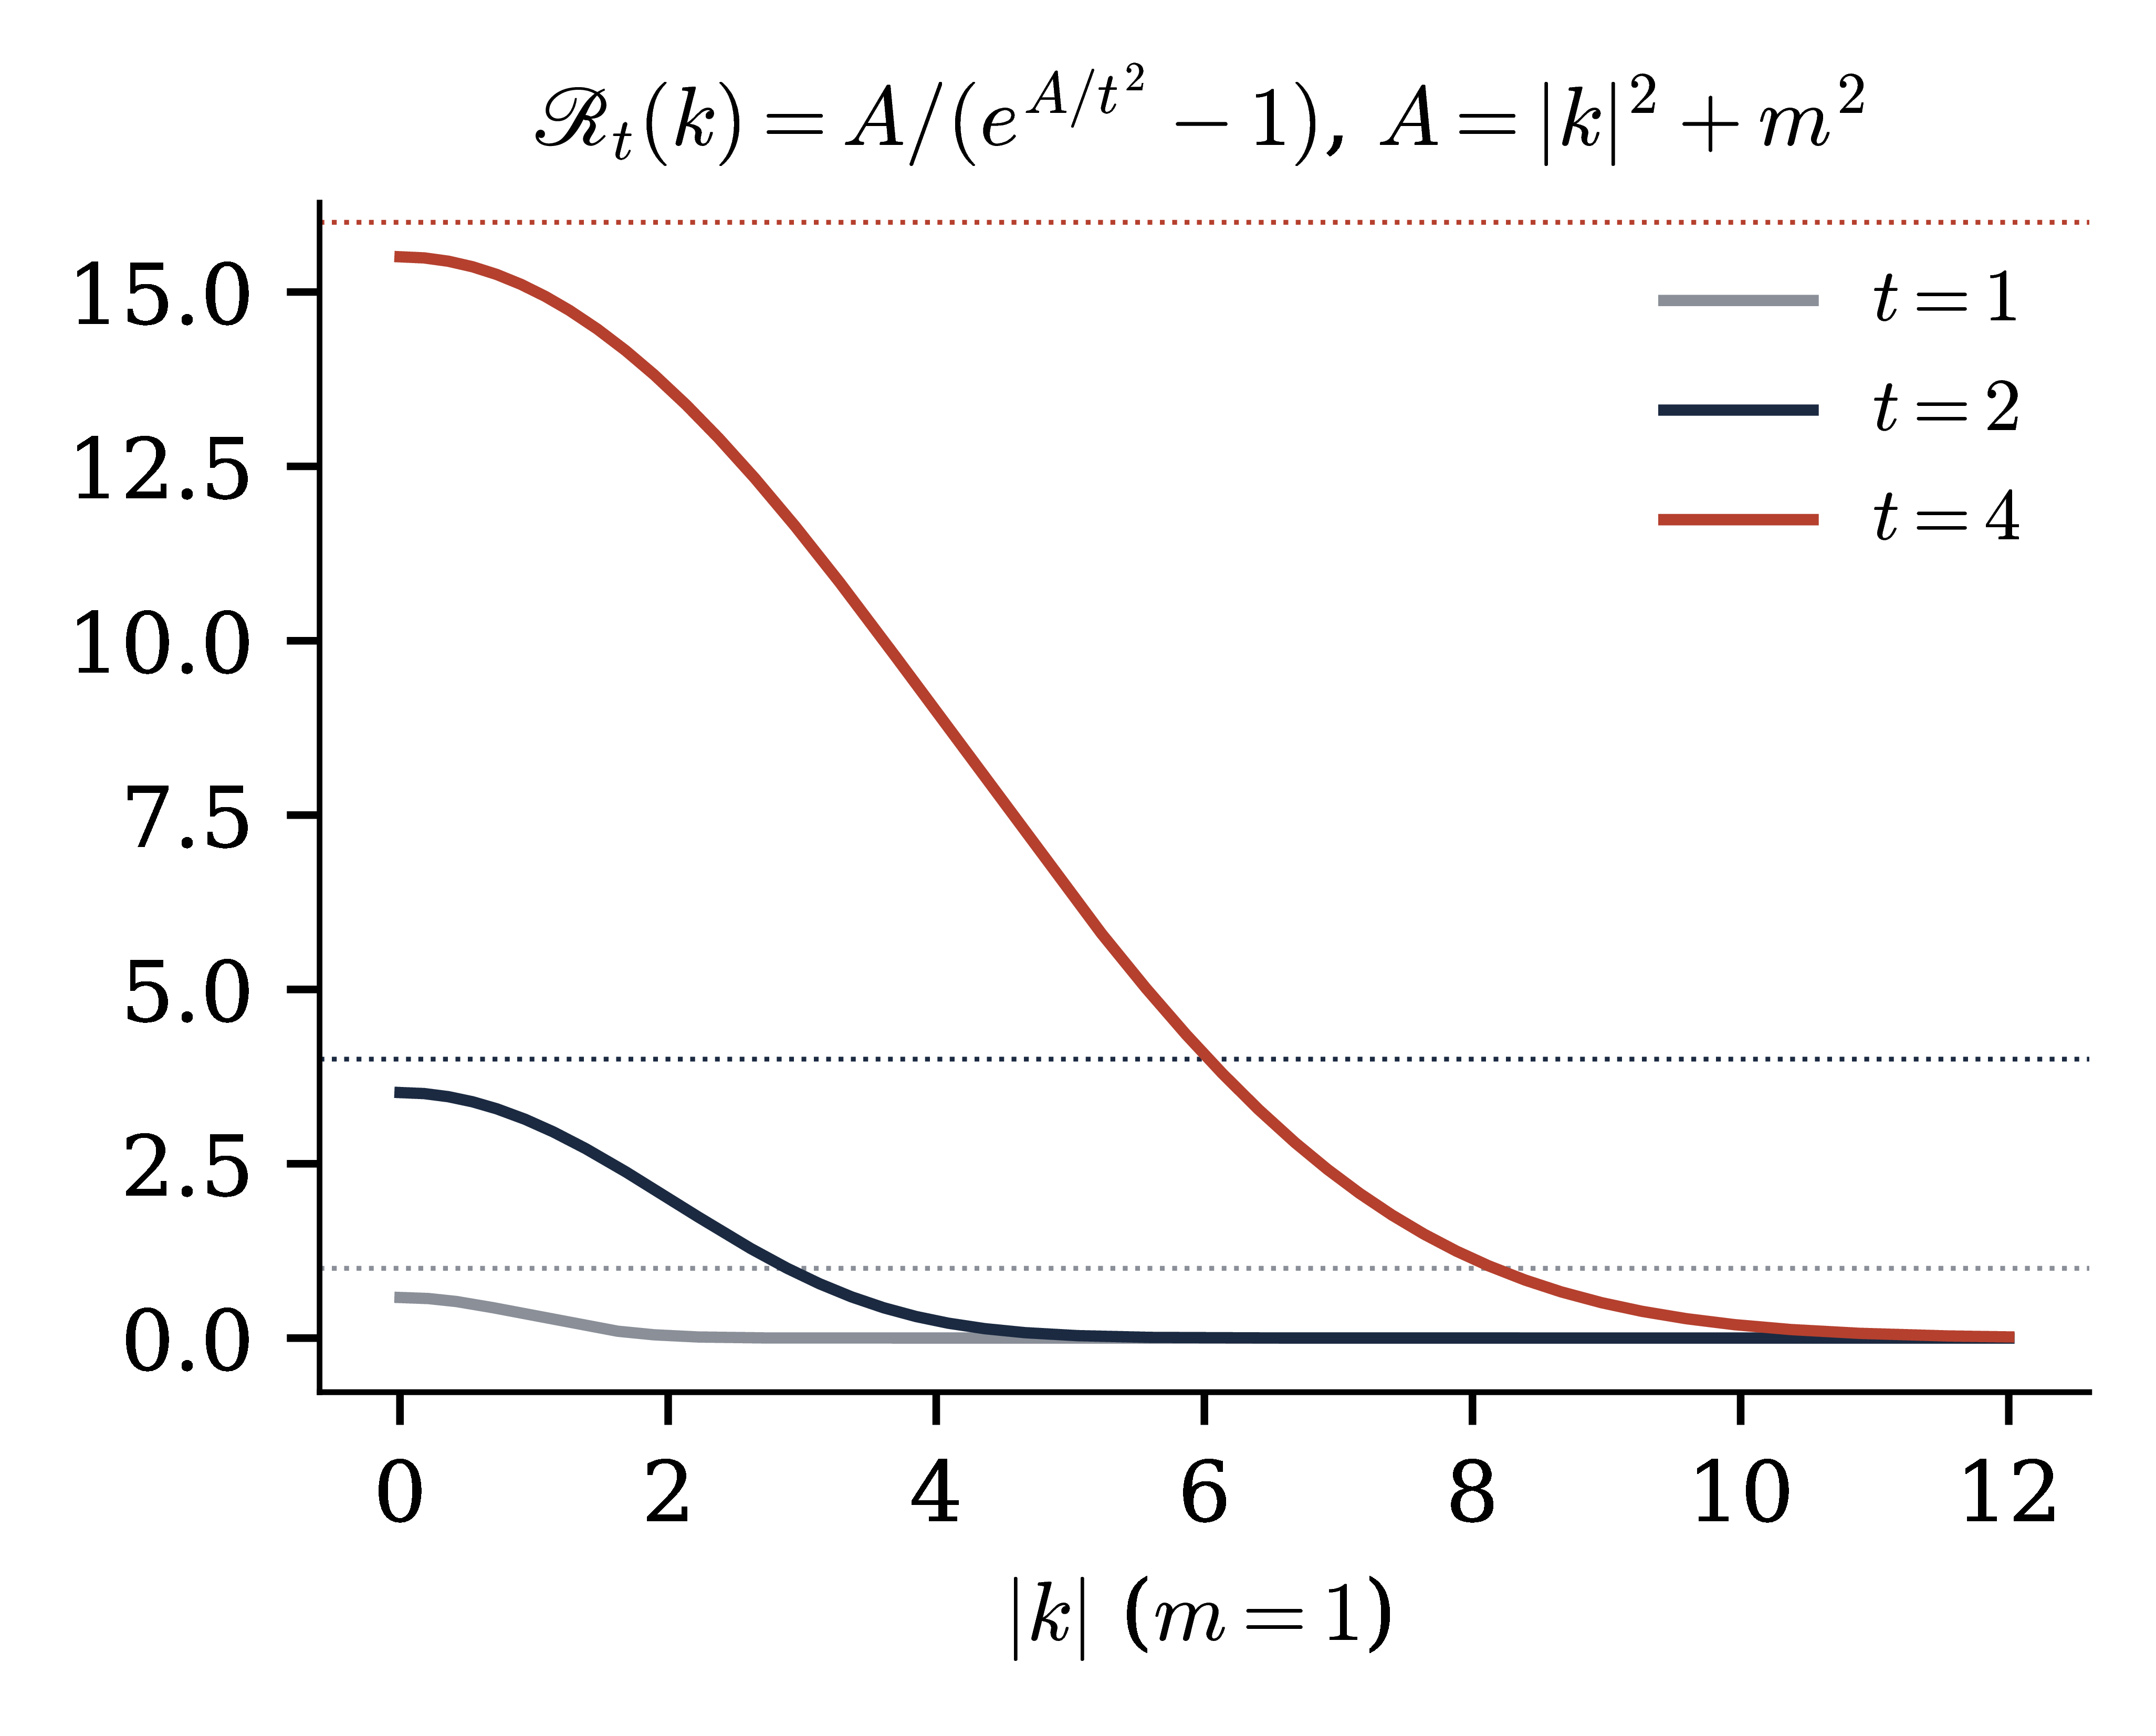
The flow of \(\Gamma\) is driven by the difference between the interacting and the free conditional covariances, paired with the shell \(\dot{\mathcal{R}}_t\). It is one-loop exact, with the full propagator inside the trace. In the Gaussian case \(\mathrm{D}^2 \Gamma_t\) is constant and only the constant term of \(\Gamma\) flows. For the heat profile with \(T = \infty\), \(S_t = C (1 - \mathrm{e}^{- A / t^2})\) and
| \(\displaystyle \mathcal{R}_t = \frac{A}{\mathrm{e}^{A / t^2} - 1},\) | (8.15) |
which behaves like a mass term \(t^2\) on the modes \(|k| \ll t\) (for \(m \ll t\)) and is exponentially small on the modes \(|k| \gg t\): the exponential regulator of the functional renormalisation group (Figure 8.5).
Proposition
up to a function of \(t\), and differentiating at fixed \(\psi\) gives the Wetterich equation (8.13) again.
Proof. By (8.12) and the formula
for \(\mathcal{K}\). At fixed \(\psi\), with \(j = \mathrm{D}
\mathcal{K}^{\ast} (\psi)\), the envelope theorem and
and \(\partial_t \frac{1}{2} \langle \psi, S^{- 1} \psi \rangle = \frac{1}{2} \langle \psi, \dot{\mathcal{R}} \psi \rangle\). Hence \(\partial_t \Gamma_t = \frac{1}{2} \text{Tr} (\dot{\mathcal{R}} \text{Cov})\) up to a function of \(t\), which is \(- \frac{1}{2} \text{Tr} (\dot{\mathcal{R}} S)\) with the normalisation (8.12).\(\Box\)
So one Lagrangian graph has three generators: \(V_t\) in the field \(x\), \(\mathcal{K}_t\) in the coordinate \(j = S_t^{- 1} x\) of Remark 7.8, and \(\Gamma_t\) in the forecast \(\psi\). The Polchinski flow is the Hamilton–Jacobi equation of the log-partition function of the localisation; the Wetterich flow is its Legendre dual [Mor94], whose argument is the posterior mean, and whose regulator is the information gained. At \(t = 0\), where \(\mathcal{R}_0 = 0\), \(\mathcal{K}_0\) is the generating function \(\Lambda\) of the cumulants of \(\nu_T\) below.
the generating functional of the vertex functions introduced by Jona-Lasinio [JL64]. It is a probabilistic object, as Jona-Lasinio emphasised in his probabilistic reading of the renormalisation group [JL75, JL01]; for the link with large deviations see Section VIII of [JL01]. By Cramér's theorem the empirical mean of \(N\) independent samples of \(\nu_T\) takes the value \(\psi\) with probability
so \(\Gamma^{\text{EAA}}_0 - V_0 (0)\) is the rate function of the large deviations of averages of the field. In particular \(\Gamma^{\text{EAA}}_0\) is convex even when \(V_T\) is not, it is minimal at the mean of \(\nu_T\), and its Hessian there is the inverse covariance. Formally the same holds for the field averaged over a large volume, with the volume as the large parameter and the effective potential of quantum field theory (\(\Gamma\) per unit volume at constant \(\psi\), not \(V_t\)) as rate function; in that limit flat parts may appear (the Maxwell construction).
for \(\nu\) of mean \(\psi\),
So \(\Gamma_t\), the effective average action up to the quadratic term
\(\frac{1}{2} \langle \psi, Q_T^{- 1} \psi \rangle\), is the free
energy of the unresolved shell constrained to the forecast \(\psi\), and
| \(\displaystyle V^{\text{tree}}_t (x) = \inf_y \left\{ V_T (y) + \tfrac{1}{2} \langle y - x, S_t^{- 1} (y - x) \rangle \right\},\) | (8.17) |
the solution of the noiseless Polchinski equation \(\partial_t V =
\frac{1}{2} \langle \mathrm{D} V, \dot{Q} \mathrm{D} V \rangle\). It is
the saddle point of the Gaussian convolution
Exercise
Exercise
Exercise
Exercise
Exercise
Exercise
Exercise
Exercise
Exercise
Exercise
In Lecture 3 the primary objects were the stochastic observables, martingales in the filtration of finite-resolution measurements [BCG26]. The filtering point of view makes this natural: an observable is a posterior mean \(\mathbb{E}_t [G (\Phi_T)]\). We have already met the force \(F_t\) and the forecast \(\psi_t\), and the field \(\Phi_t\) is not one of them. This section develops the language for the interacting theory, and then draws the main consequence of the filter: a field equation at every resolution, with a noise whose moments are controlled a priori.
For a functional \(G\) of the terminal field, the observable \(O_t =\mathbb{E}^{\mathbb{P}}_t [G (\Phi_T)]\) is \(O_t = G_t (\Phi_t)\), with
| \(\displaystyle G_t (\phi) = \mu_t^{\phi} (G) = \mathrm{e}^{V_t (\phi)} \int G (\phi + \zeta) \hspace{0.17em} \mathrm{e}^{- V_T (\phi + \zeta)} \mu^{Q_{T, t}} (\mathrm{d} \zeta) .\) | (9.1) |
Formally, \(G_t\) solves the backward Kolmogorov equation of the interacting dynamics,
| \(\displaystyle \partial_t G_t + \tfrac{1}{2} \text{Tr} (\dot{Q}_t \mathrm{D}^2 G_t) - \langle \dot{Q}_t \mathrm{D} V_t, \mathrm{D} G_t \rangle = 0, \qquad G_T = G,\) | (9.2) |
which is the Doob transform of the Gaussian heat equation by
\(\mathrm{e}^{- V_t}\) (Exercise 9.1). Conversely, any
solution of
| \(\displaystyle \partial_{\theta} \mathbb{E}^{\nu^{\theta}_T} [G] = - \text{Cov}^{\nu_T^{\theta}} (G, \partial_{\theta} V^{\theta}_T) .\) | (9.3) |
Thus the tangent observables, such as the running \(: \varphi^4\): for \(\theta = \lambda\) (together with the derivative of the counterterm \(\partial_{\lambda} \gamma_T \int : \varphi^2\):), describe the response of the theory to a change of coupling. They are the observables conjugate to the coordinates of theory space.
By
Theorem
| \(\displaystyle \eta_t := K \Phi_t - J_t F_t\) | (9.4) |
is a centred \(\mathbb{P}\)-martingale, with \(\mathrm{d} \eta_t = K \dot{Q}_t^{1 / 2} \mathrm{d} W_t - J_t \hspace{0.17em} \mathrm{d} F_t\). For every \(t \leqslant T\), every \(h\) and every functional \(G\),
At \(t = T\) this is the Dyson–Schwinger equation of \(\nu_T\),
Proof. From
Take \(k = Kh\), so that \(Q_t k = J_t h\), and recall \(F_t = - \mathrm{D} V_t (\Phi_t)\).\(\Box\)
Formally letting \(T \to \infty\), \(K \to A\), and
| \(\displaystyle A \Phi_t = AQ_t \hspace{0.17em} F_t + \eta_t,\) | (9.7) |
with \(AQ_t = \mathrm{e}^{- A / t^2}\) for the heat profile. This is the
Euclidean field equation \(A \varphi = - V' (\varphi) +\)noise of
Lectures 1–2, seen at resolution \(t\). It needs no products of
distributions: the nonlinearity enters only through the force
observable \(F_t\), smeared at scale \(1 / t\). For the GFF
(\(F = 0\)),
| \(\displaystyle K \psi_t = F_t + \eta_t, \qquad F_t = - \mathrm{D} \Gamma_t (\psi_t) .\) | (9.8) |
As \(T \to \infty\) the two forms of the field equation at resolution \(t\) are
In the first, the force is smeared by \(\mathrm{e}^{- A / t^2}\) so the
nonlinearity is seen only through a smoothing operator. In the second it
acts on the same variable as the linear part, with no smoothing: this is
the Euler–Lagrange equation of the action \(\frac{1}{2} \langle
\psi, A \psi \rangle + \Gamma_t (\psi)\), forced by the noise
\(\eta_t\). For \(\Phi^4\), at finite \(T\) and to first order in
\(\lambda\), the Wetterich equation
and since \(\partial_c H_4 = - 6 H_2\) and \(c_T - S_t (x, x) = c_t\), the one loop moves the Wick ordering from the cutoff to the resolution:
The cube acts directly on the forecast, and pairing with \(\psi_t\) gives
where \(4 a^4 - 12 c_t a^2 \geqslant - 9 c_t^2\) and \(c_t\) is finite at fixed \(t\): heuristically, a coercive bound up to a volume constant, driven by the sub-Gaussian noise of Section 9.3. With the bare Wick ordering \(c_T\) the quadratic term would diverge; in \(d = 3\) only the mass counterterm \(\gamma_T\), of order \(\lambda^2\), still does. In the form for \(\Phi_t\) the same positivity is hidden behind \(\mathrm{e}^{- A / t^2}\).
The integration by parts formula
The direction of differentiation is now random, the conditional covariance applied to \(\mathcal{R}_t h\).
Remark
Corollary
| \(\displaystyle \mathbb{E} [G \langle \eta_t, h \rangle] =\mathbb{E} \sum_{i = 1}^k (\partial_i g) (\cdots) \langle J_{t_i} h, h_i \rangle, \) | (9.9) |
that is, the derivative of \(G\) in the direction which shifts the field at each scale \(s\) by \(J_s h\). The increments are consistent: \(\mathbb{E} [G \langle \eta_t - \eta_s, h \rangle] = 0\) for \(t_k \leqslant s \leqslant t\).
Proof. \(G\) is \(\mathcal{F}_t\)-measurable, so
\(\mathbb{E} [G \langle \eta_t, h \rangle] =\mathbb{E} [G \langle S_t^{-
1}
\zeta_t, h \rangle]\). By
Remark
The noise observable \(\eta_t\) is not Gaussian: it depends on the unknown law of the interacting field. But the filter says what it is, the conditional expectation of the rescaled bridge noise \(S_t^{- 1} \zeta_t\), so its moments are bounded by those of an explicit Gaussian, uniformly in the interaction.
Work at finite cutoff, where \(\Phi_t\) has a Lebesgue density \(p_t\), and let \(0 < t < T\). By Proposition 7.2,
and since \(J_t Q_t^{- 1} = K\),
| \(\displaystyle \eta_t = - J_t \mathrm{D} \log p_t (\Phi_t) . \) | (9.10) |
The noise is the score of the law of the field at resolution \(t\), seen through \(J_t\).
Only deterministic covariance operators, all functions of \(A\), are
commuted below. The variance that appears is the regulator
| \(\displaystyle J_t^2 (Q_t (1 - J_t))^{- 1} = KJ_t (1 - J_t)^{- 1} = S_t^{- 1} - Q_T^{- 1} =\mathcal{R}_t . \) | (9.11) |
Proposition
and \(\eta_t\) is dominated in the convex order by \(N (0, \mathcal{R}_t)\):
\(\Xi \sim N (0, \mathcal{R}_t)\), for every convex \(\Psi\) for which both sides are defined. In particular, for every \(h\) and \(u \in \mathbb{R}\),
| \(\displaystyle \mathbb{E} \mathrm{e}^{u \langle h, \eta_t \rangle} \leqslant \exp \left( \frac{u^2}{2} \langle h, \mathcal{R}_t h \rangle \right) : \) | (9.12) |
every smeared noise observable is centred and sub-Gaussian, with the regulator as variance and with no convexity assumption on the interaction.
Proof. Write \(\Sigma_t = Q_t (1 - J_t)\), so that \(J_t \Sigma_t^{- 1} = S_t^{- 1}\), and \(g\) for the density of \(N (0, \Sigma_t)\). Then
and \(\mathrm{D} g (z) = - \Sigma_t^{- 1} z \hspace{0.17em} g (z)\), so
apply \(J_t\) and use
and \(S_t^{- 1} \zeta_t\) is centred Gaussian with covariance \(S_t^{- 1} \Sigma_t S_t^{- 1} =\mathcal{R}_t\).\(\Box\)
For the heat profile (compare
(Exercise 9.5). At a finite spatial cutoff all of this holds with terminal resolution \(T = \infty\), before any continuum measure is constructed.
Since \(x / (\mathrm{e}^x - 1) \leqslant \mathrm{e}^{- x / 2}\),
\(\mathcal{R}_t \leqslant t^2 \mathrm{e}^{- A / 2 t^2}\): at resolution
\(t\) the noise is no larger than \(t\) times a white noise smoothed at
scale \(1 / t\). Pointwise, \(\operatorname{Var} \hspace{0.17em} \eta_t
(x) \leqslant \mathcal{R}_t (x, x)
\lesssim t^{d + 2}\), i.e. \(\eta_t
(x) = O (t^{1 + d / 2})\). This is the size at scale \(1 / t\) of a
distribution of regularity \(- 1 - d / 2\) (\(- 5 / 2\) in \(d = 3\)):
seen at its own resolution, the noise is one derivative rougher than
white noise (\(- d / 2\)) and two rougher than the GFF (\(1 - d / 2\)),
the same as the GFF noise \(A \varphi = A^{1 / 2} \xi\) of the
Dyson–Schwinger equation, whatever the interaction. It is not a
bound on a limit distribution: \(\eta_t\) is a martingale in \(t\), not
the smoothing of a fixed distribution, and on a fixed test function
Remark
is convex, so Proposition 9.5 dominates \(\| \eta_t \|_{\varepsilon}\) by \(\| \Xi \|_{\varepsilon}\), with \(\Xi \sim N (0, \mathcal{R}_t)\). For this Gaussian field, \(\mathcal{R}_t (x, x) \lesssim t^{d + 2}\) and
so Dudley's bound and Gaussian concentration give Gaussian tails for \(\| \Xi \|_{\varepsilon}\) at the level \(t^{1 + d / 2} \sqrt{\log (2 + t)}\), uniformly in \(L\). Since \(\eta\) is a martingale, \(\| \eta_s \|_{\varepsilon}\) is a submartingale, and Doob's inequality extends the tails to \(\sup_{s \leqslant t}\). Summing over dyadic \(t\), almost surely
with \(C\) having Gaussian tails uniformly in the interaction and in the spatial cutoff. This is a pathwise bound at each resolution, in the sense above.
so
Itô's isometry, \((a + b)^2 \leqslant 2 a^2 + 2 b^2\) and
| \(\displaystyle \mathbb{E} \int_0^t \| \Upsilon_s^{\ast} J_s h \|^2 \mathrm{d} s \leqslant 2 \langle h, \mathcal{R}_t h \rangle + 2 \langle h, KQ_t Kh \rangle . \) | (9.13) |
For the heat profile with \(T = \infty\), \(KQ_t K = A \mathrm{e}^{- A / t^2} \leqslant t^2 / \mathrm{e}\), so the right-hand side is at most \(2 (1 + \mathrm{e}^{- 1}) t^2 \|h\|_{L^2}^2\). This controls a smoothed derivative of the force, \(\Upsilon_s = \mathrm{D} F_s (\Phi_s) \dot{Q}_s^{1 / 2}\), without any estimate on the terminal force.
On \(\mathbb{T}^d_L\) the free energy \(V_0 (0)\) and the effective
potential \(V_t\) are extensive: they grow like \(L^d\), and
the force. For a local interaction \(V_T (\varphi) = \int
v_T (\varphi (x)) \mathrm{d} x\), \(\mathrm{D} V_T (\varphi) (x) =
v_T' (\varphi (x))\), and
| \(\displaystyle \Phi_t = \int_0^t \dot{Q}_s F_s \hspace{0.17em} \mathrm{d} s + \int_0^t \dot{Q}_s^{1 / 2} \mathrm{d} W_s, \qquad F_t (x) = -\mathbb{E}_t [v_T' (\Phi_T (x))] .\) | (9.14) |
Here every quantity is local, and the equation makes sense without
a volume cutoff. Infinite-volume limits of \(\nu_T^{(L)}\) are
expected to be laws of solutions of
the Burgers flow
differences of free energies. For a local \(f\),
\(\mathcal{W}_T^{(L)} (f)\) in
Proposition
where the infimum runs over adapted \(w\) with \(\mathbb{E} \int_0^T \|w_s \|^2 \mathrm{d} s < \infty\), and
is the remainder of the first-order Taylor expansion of \(V\). The minimiser satisfies \(w_s = - \dot{Q}_s^{1 / 2} \mathbb{E}_s [\mathrm{D} f (\Phi^f_T) + \mathrm{D} V_T (\Phi^f_T) - \mathrm{D} V_T (\Phi_T)]\), with \(\Phi^f = \Phi + I (w)\): the perturbed field solves the FBSDE with terminal potential \(V_T + f\), and its force is that of \(\Phi\) corrected by \(F^f_s - F_s = -\mathbb{E}_s [\mathrm{D} f (\Phi^f_T) + \mathrm{D} V_T (\Phi^f_T) - \mathrm{D} V_T (\Phi_T)]\).
Proof. By
Writing \(u = u^{\ast} + w\) and expanding \(\frac{1}{2} \|u^{\ast} +
w\|^2\), the terms \(V_T (\Phi_T)\) and \(\frac{1}{2} \int \|u^{\ast}
\|^2\) cancel against \(J_0 (u^{\ast})\), and the cross term is computed
above. The first-order condition in \(w\) is obtained as in
For a local interaction \(V_T (\varphi) = \int v_T (\varphi (x)) \mathrm{d} x\),
and \(b_T (a, 0) = 0\). So every term of
an infinite-volume measure is the law of \(\Phi_T\) for a solution
\(\Phi\) of
The Laplace functionals in
The coercive estimates must then be local: one uses weighted norms and needs bounds whose constants do not depend on the volume. This infrared problem is the analogue, for the scale dynamics, of the “coming down from infinity” estimates for the parabolic dynamics.
Exercise
Exercise
Exercise
Exercise
Exercise
For a positive covariance \(S\) define the renormalisation map
| \(\displaystyle \mathcal{R}_S (V) := - \log (\mu^S \ast \mathrm{e}^{- V}), \qquad (\mu^S \ast u) (\phi) = \int u (\phi + \zeta) \mu^S (\mathrm{d} \zeta) .\) | (A.1) |
Since \(\mu^S \ast \mu^{S'} = \mu^{S + S'}\),
| \(\displaystyle \mathcal{R}_S \circ \mathcal{R}_{S'} =\mathcal{R}_{S + S'} =\mathcal{R}_{S'} \circ \mathcal{R}_S, \qquad V_t =\mathcal{R}_{Q_{T, t}} (V_T) .\) | (A.2) |
So the effective potentials are an orbit of an abelian semigroup, indexed by the cone of positive covariances, acting nonlinearly on interactions and linearly on Boltzmann factors \(\mathrm{e}^{- V}\). Its infinitesimal generators are the vector fields
and
Proposition
Proof. (a) Differentiate \(\mathcal{R}_{sB}
\mathcal{R}_{rB'} =\mathcal{R}_{rB'} \mathcal{R}_{sB}\) at \(s = r =
0\), or compute directly (Exercise A.1). (b) is
Different profiles with the same endpoints are different coordinate systems on the same renormalisation group trajectory. They change the process \(\Phi\) and the observables at intermediate resolution, but not the terminal theory. The flow has no holonomy [BCG26].
Expanding \(V_t =\mathcal{R}_{Q_{T, t}} (V_T)\) in cumulants of the Gaussian increment \(\zeta \sim \mu^{Q_{T, t}}\) gives
| \(\displaystyle V_t (\phi) =\mathbb{E}_{\zeta} [V_T (\phi + \zeta)] - \tfrac{1}{2} \text{Var}_{\zeta} (V_T (\phi + \zeta)) + \ldots\) | (A.4) |
For
| \(\displaystyle V_t (\phi) = \int \left[ \frac{\lambda}{12} H_4 (\phi (x) ; c_t) + \gamma_T H_2 (\phi (x) ; c_t) \right] \mathrm{d} x + O (\lambda^2) .\) | (A.5) |
Here \(\gamma_T = O (\lambda^2)\) is kept for later use. At first order the effective potential is the Wick-ordered potential at the current resolution. This is the dual statement of Proposition 6.1 of Lecture 3: \(\int H_4 (X_t ; c_t)\) is an observable.
Proposition
up to \(O (\lambda^3)\).
Proof. By the binomial formula for Hermite polynomials,
Then compute the variance in
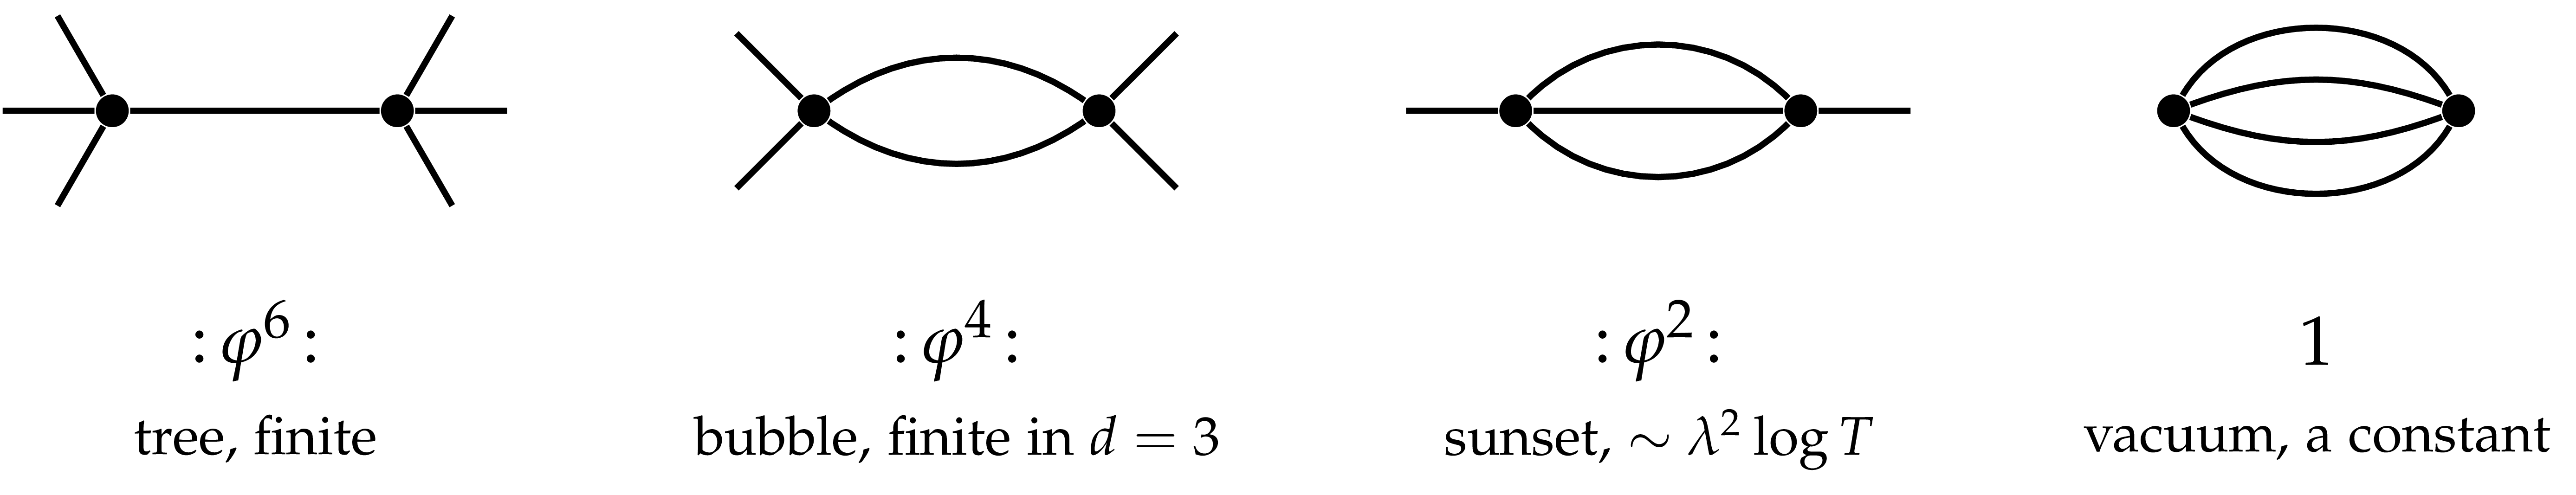
|
Figure A.1. The terms \(k = 1, 2,
3, 4\) of |
Now let \(T \to \infty\) at fixed \(t\), so that \(S \to C - Q_t\), which near the diagonal is as singular as \(G\). In \(d = 2\) every \(S^k\) is locally integrable, so with \(\gamma_T = 0\) every term has a limit: Wick ordering suffices. In \(d = 3\), \(G (z) \sim (4 \pi |z|)^{- 1}\):
\(k = 1, 2\): \(S\) and \(S^2\) are locally integrable. These terms are finite and nonlocal.
\(k = 3\) (the sunset): \(S^3 \sim |z|^{- 3}\) is not integrable. Writing \(\phi (x) \phi (y) = \frac{1}{2} (\phi (x)^2 + \phi (y)^2) - \frac{1}{2} (\phi (x) - \phi (y))^2\), up to a field-independent constant the divergent part is local:
with \(\int S^3 \sim \frac{1}{16 \pi^2} \log T\). It is cancelled by
| \(\displaystyle \gamma_T := \frac{\lambda^2}{3} \int_{\mathbb{T}^3_L} Q_T (z)^3 \hspace{0.17em} \mathrm{d} z = \frac{\lambda^2}{48 \pi^2} \log T + O (1),\) | (A.7) |
since \(\gamma_T - \frac{\lambda^2}{3} \int S^3\) converges (Exercise A.2).
\(k = 4\): a divergent constant \(- \frac{\lambda^2}{12} L^3 \int S^4 \sim T\), the vacuum energy. It cancels in \(\nu_T\) but not in the free energy.
Power counting (Exercise A.3) shows that no further field-dependent counterterms are needed in \(d = 3\): \(\Phi^4_3\) is superrenormalisable. Thus renormalisation appears as a property of the flow: one chooses the terminal data \(V_T\) so that the effective potentials \(V_t\) at fixed resolution have limits. The divergences at second order are also related to the singularity of \(\Phi^4_3\) with respect to the GFF [BG21]: the measures \(\nu_t\) at fixed \(t\) are expected to stay absolutely continuous with respect to \(\mu^{Q_t}\), while the terminal one is not.
Exercise
Exercise
Exercise
Proposition 7.2 and Section 7.3 say that the Polchinski process is a stochastic localisation of \(\nu_T\). This appendix records why that decomposition is useful, and what it proves.
It is a martingale. \(\nu_T =\mathbb{E} \mu_t^{\Phi_t}\), and the expectation of any test function under \(\mu_t^{\Phi_t}\) is a martingale. Itô calculus then splits variance and entropy exactly into the part already revealed and the part still hidden.
The pieces are simpler. The Gaussian factor adds \(\mathcal{R}_t\) to the Hessian of the potential. If \(\nu_T\) is log-concave, \(\mu_t^{\phi}\) is \(\mathcal{R}_t\)-uniformly log-concave, so Bakry–Émery and Brascamp–Lieb apply to it even when their constants are useless for \(\nu_T\) itself.
One quantity controls the loss. What is revealed per unit
resolution is governed by \(\operatorname{Cov}_t\), whose evolution
The process can also be run as an algorithm: with an approximate force
it is a sampler, as in the algorithmic stochastic localisation of [EMS22], and denoising diffusions are of the same kind [Mon23]. By
Bauerschmidt and Bodineau [BB21] proved log-Sobolev inequalities by running the Polchinski flow (see the survey [BBD24]). In their language the renormalised measure at a given scale is the law of \(\Phi_t\), and the fluctuation measure is the conditional law \(\mu_t^{\Phi_t}\) of Proposition 7.2, i.e. the stochastic localisation of \(\nu_T\) [Eld23]. (Their scale parameter runs opposite to our resolution: their initial scale is our \(T\), where the renormalised measure is \(\nu_T\) and the fluctuation measure is trivial, and their integrated covariance is our \(S_t\).) In this dictionary their argument is an entropy computation along our filtration.
and, stopping at resolution \(t\), the chain rule
the entropy already revealed at resolution \(t\) plus the expected entropy still hidden. The increments are controlled by the conditional law: differentiating the density of \(\mu_t^{\phi}\) in \(\phi\), \(\mathrm{D} G_t (\phi) = S_t^{- 1} \operatorname{Cov}_{\mu_t^{\phi}} (\rho, y)\).
Theorem
Then \(\nu_T\) satisfies the log-Sobolev inequality
The hypothesis gives, at each resolution, the gradient bound
inserted in the entropy formula it gives the theorem [BBD24]. For \(V_T = 0\) and a linear profile \(Q_t = tQ_T / T\) one may take \(\kappa = 0\), so \(1 / \gamma = T\) and the theorem is the Gaussian log-Sobolev inequality \(\operatorname{Ent} (\rho) \leqslant 2\mathbb{E} \langle D \sqrt{\rho}, Q_T D \sqrt{\rho} \rangle\). The hypothesis is a convexity condition on the effective potentials at every scale, not on \(V_T\), corrected by the scale dependence \(\ddot{Q}_t\) of the decomposition; \(\kappa_t\) may be negative at some scales: only the weights \(\mathrm{e}^{- 2 \int_t^T \kappa_r \mathrm{d} r}\) enter \(\gamma\).
If \(\dot{Q}_t\) is invertible, multiplying on the left by \(S_t \dot{Q}_t^{- 1} = \dot{\mathcal{R}}_t^{- 1} S_t^{- 1}\) and on the right by its transpose \(\dot{Q}_t^{- 1} S_t\) shows that it is equivalent to the explicit bound
| \(\displaystyle \operatorname{Cov}_{\mu_t^{\phi}} \leqslant S_t - S_t \dot{Q}_t^{- 1} \left( \kappa_t \dot{Q}_t - \frac{1}{2} \ddot{Q}_t \right) \dot{Q}_t^{- 1} S_t \qquad \forall \phi . \) | (B.1) |
The second derivative \(\ddot{Q}_t\) is not estimated: it is a property of the Gaussian decomposition, and it enters only through the combination \(\kappa_t \dot{Q}_t - \frac{1}{2} \ddot{Q}_t\). When \(Q_t\) and \(S_t\) are functions of one operator (Fourier multipliers, say), the right-hand side is \(S_t - S_t^2 \dot{Q}_t^{- 2} (\kappa_t \dot{Q}_t - \frac{1}{2} \ddot{Q}_t)\) mode by mode. If \(\kappa_t \dot{Q}_t > \frac{1}{2} \ddot{Q}_t\) (for the linear profile: \(\kappa_t > 0\)), every conditional law is strictly more concentrated than the unresolved Gaussian fluctuation; if not, \(\operatorname{Cov}_t\) may exceed \(S_t\), as in a double well at low resolution. A concave profile (\(\ddot{Q} \leqslant 0\)) makes the bound smaller but forces \(\kappa\) down by the same amount: for the Gaussian with \(Q_t = 1 - \mathrm{e}^{- t}\) one has \(\ddot{Q} = - \dot{Q}\), the hypothesis holds with \(\kappa = - \frac{1}{2}\), and \(\operatorname{Cov}_t = S_t\). The hypothesis is thus an upper bound on the conditional covariance, uniform in the conditioning, measured in the metric \(\dot{\mathcal{R}}_t\). Closely related is the entropic stability of Chen and Eldan [CE22] (see also [BBD24]): if, for all \(r \leqslant t\) and all \(\phi\), \(\dot{\mathcal{R}}_r \operatorname{Cov}_{\mu_r^{\phi}} \dot{\mathcal{R}}_r \leqslant \alpha_r \dot{\mathcal{R}}_r\), then
the total entropy is controlled by the entropy that is still hidden at resolution \(t\). The low-resolution part of the localisation is where the measure may be multimodal, and the condition says that it does not hide too much. With the Brascamp–Lieb bounds of Section 8.4 the conditional covariance is controlled by the Hessian of \(V_T\) when this is convex; for \(\Phi^4_3\) it is not, and the condition is a statement about the effective potentials, i.e. about the renormalisation group flow itself.
Proposition
If moreover \(\nu_T\) is log-concave, then
Proof. Let \(M_r =\mathbb{E}_r f (\Phi_T)\) and \(\chi_r =\operatorname{Cov}_{\mu_r^{\Phi_r}} (f, y)\). As in Section B.1, \(\mathrm{d} \langle M \rangle_r = \langle \chi_r, \dot{\mathcal{R}}_r \chi_r \rangle \mathrm{d} r\), so \(v (r) := \mathbb{E}\operatorname{Var}_{\mu_r^{\Phi_r}} (f)\) has \(v' = -\mathbb{E} \langle \chi_r, \dot{\mathcal{R}}_r \chi_r \rangle\) and \(v (0) =\operatorname{Var}_{\nu_T} (f)\). By Cauchy–Schwarz, with \(h = \dot{\mathcal{R}}_r \chi_r\), \(\langle \chi_r, h \rangle^2 \leqslant \operatorname{Var}_{\mu_r^{\Phi_r}} (f) \langle h, \operatorname{Cov}_r h \rangle \leqslant \alpha_r \operatorname{Var}_{\mu_r^{\Phi_r}} (f) \langle \chi_r, \dot{\mathcal{R}}_r \chi_r \rangle\). Hence \(v' \geqslant - \alpha_r v\), which gives the first bound. For the second, the Hessian of the potential of \(\mu_t^{\phi}\) is at least \(\mathcal{R}_t\): apply Brascamp–Lieb to \(\mu_t^{\phi}\) and take the expectation.\(\Box\)
For \(V_T = 0\) one has \(\operatorname{Cov}_r = S_r\). In one mode, or for the linear profile, where \(\dot{Q}_r S_r^{- 1}\) is a number, \(\alpha_r = \dot{Q}_r S_r^{- 1}\) and \(\exp \int_0^t \alpha_r \mathrm{d} r = Q_T S_t^{- 1}\): the first bound is an equality for linear \(f\), and the second tends to the Gaussian Poincaré inequality as \(t \to T\) (Exercise B.2).
this lecture
Bauerschmidt–Bodineau
stochastic localisation
resolution \(t\) increasing
their scale, reversed
time \(t\) increasing
law \(\nu_t\) of \(\Phi_t\)
renormalised measure
law of the tilt
\(\mu_t^{\phi}\)
fluctuation measure
tilted measure
\(S_t\), \(\mathcal{R}_t\)
integrated covariance, —
—, \(t\)
\(G_t = \int \rho \mathrm{d} \mu_t^{\phi}\)
Polchinski semigroup on \(\rho\)
martingale \(\int \rho \mathrm{d} \mu_t\)
\(\mathrm{D}^2 V_t = S_t^{- 1} - S_t^{- 1}
\operatorname{Cov}_t S_t^{- 1}\)
Hessian of the potential
covariance of the tilted measure
Proposition 8.3 is the bridge: convexity of the
renormalised potentials is an upper bound on the conditional covariance,
namely
Bauerschmidt–Bodineau. The Kolmogorov equation
Localisation. One bounds what is lost on \([0, t]\) (the proposition above, or entropic stability [CE22]) and uses a known inequality for \(\mu_t^{\phi}\). It works directly with moments of the conditional law, and can use bounds that hold only with high probability along the path, as in the KLS problem.
Exercise
Exercise
S. Albeverio, S. Liang, B. Zegarlinski. Remark on the integration by parts formula for the \(\varphi^4_3\)-quantum field model. Infin. Dimens. Anal. Quantum Probab. Relat. Top. 9 (2006), 149–154.
A. El Alaoui, A. Montanari. An information-theoretic view of stochastic localization. Preprint, arXiv:2109.00709, 2021.
B. D. O. Anderson. Reverse-time diffusion equation models. Stochastic Process. Appl. 12 (1982), 313–326.
R. Bauerschmidt, T. Bodineau. A very simple proof of the LSI for high temperature spin systems. J. Funct. Anal. 276 (2019), 2582–2588.
R. Bauerschmidt, T. Bodineau. Log-Sobolev inequality for the continuum sine-Gordon model. Comm. Pure Appl. Math. 74 (2021), 2064–2113.
R. Bauerschmidt, T. Bodineau, B. Dagallier. Stochastic dynamics and the Polchinski equation: an introduction. Probab. Surveys 21 (2024), 200–290.
I. Bailleul, I. Chevyrev, M. Gubinelli. Stochastic observables and Wilson–Itô diffusions. In preparation.
M. Boué, P. Dupuis. A variational representation for certain functionals of Brownian motion. Ann. Probab. 26 (1998), 1641–1659.
N. Barashkov, M. Gubinelli. A variational method for \(\Phi^4_3\). Duke Math. J. 169 (2020), 3339–3415.
N. Barashkov, M. Gubinelli. The \(\Phi^4_3\) measure via Girsanov's theorem. Electron. J. Probab. 26 (2021), 1–29.
N. Barashkov, M. Gubinelli. On the variational method for Euclidean quantum fields in infinite volume. Probab. Math. Phys. 4 (2023), 761–801.
J.-M. Bismut. Conjugate convex functions in optimal stochastic control. J. Math. Anal. Appl. 44 (1973), 384–404.
D.C. Brydges, T. Kennedy. Mayer expansions and the Hamilton–Jacobi equation. J. Stat. Phys. 48 (1987), 19–49.
H. J. Brascamp, E. H. Lieb. On extensions of the Brunn–Minkowski and Prékopa–Leindler theorems, including inequalities for log concave functions, and with an application to the diffusion equation. J. Funct. Anal. 22 (1976), 366–389.
J. Berges, N. Tetradis, C. Wetterich. Non-perturbative renormalization flow in quantum field theory and statistical physics. Phys. Rep. 363 (2002), 223–386.
Y. Chen, R. Eldan. Localization schemes: a framework for proving mixing bounds for Markov chains. In 2022 IEEE 63rd Annual Symposium on Foundations of Computer Science (FOCS), 2022, 110–122.
Y. Chen. An almost constant lower bound of the isoperimetric coefficient in the KLS conjecture. Geom. Funct. Anal. 31 (2021), 34–61.
J. Cotler, S. Rezchikov. Renormalization group flow as optimal transport. Phys. Rev. D 108 (2023), 025003.
J. Cotler, S. Rezchikov. Renormalizing diffusion models. Preprint, arXiv:2308.12355, 2023.
B. Efron. Tweedie's formula and selection bias. J. Amer. Statist. Assoc. 106 (2011), 1602–1614.
R. Eldan. Thin shell implies spectral gap up to polylog via a stochastic localization scheme. Geom. Funct. Anal. 23 (2013), 532–569.
R. Eldan. Analysis of high-dimensional distributions using pathwise methods. In Proceedings of the ICM 2022, EMS Press, 2023, 4246–4270.
A. El Alaoui, A. Montanari, M. Sellke. Sampling from the Sherrington–Kirkpatrick Gibbs measure via algorithmic stochastic localization. In 2022 IEEE 63rd Annual Symposium on Foundations of Computer Science (FOCS), 2022.
W.H. Fleming, H.M. Soner. Controlled Markov Processes and Viscosity Solutions. 2nd ed., Stochastic Modelling and Applied Probability 25, Springer, 2006.
M. Gubinelli, M. Hofmanová. A PDE construction of the Euclidean \(\Phi^4_3\) quantum field theory. Comm. Math. Phys. 384 (2021), 1–75.
J. Glimm, A. Jaffe, T. Spencer. Phase transitions for \(\varphi^4_2\) quantum fields. Comm. Math. Phys. 45 (1975), 203–216.
J. Ho, A. Jain, P. Abbeel. Denoising diffusion probabilistic models. In Advances in Neural Information Processing Systems 33 (NeurIPS 2020), 2020. arXiv:2006.11239.
U. G. Haussmann, É. Pardoux. Time reversal of diffusions. Ann. Probab. 14 (1986), 1188–1205.
G. Jona-Lasinio. Renormalization group and probability theory. Phys. Rep. 352 (2001), 439–458.
G. Jona-Lasinio. Relativistic field theories with symmetry-breaking solutions. Nuovo Cimento 34 (1964), 1790–1795.
G. Jona-Lasinio. The renormalization group: a probabilistic view. Nuovo Cimento B 26 (1975), 99–119.
B. Klartag, J. Lehec. Bourgain's slicing problem and KLS isoperimetry up to polylog. Geom. Funct. Anal. 32 (2022), 1134–1159.
B. Klartag, J. Lehec. Affirmative resolution of Bourgain's slicing problem using Guan's bound. Preprint, arXiv:2412.15044, 2024.
B. Klartag. Logarithmic bounds for isoperimetry and slices of convex sets. Ars Inven. Anal. (2023), Paper No. 4.
A. Montanari. Sampling, diffusions, and stochastic localization. Preprint, arXiv:2305.10690, 2023.
T.R. Morris. The exact renormalization group and approximate solutions. Int. J. Mod. Phys. A 9 (1994), 2411–2449.
J. Ma, J. Yong. Forward-Backward Stochastic Differential Equations and their Applications. Lecture Notes in Math. 1702, Springer, 1999.
L. S. Pontryagin, V. G. Boltyanskii, R. V. Gamkrelidze, E. F. Mishchenko. The Mathematical Theory of Optimal Processes. Interscience, 1962.
S. Peng. A general stochastic maximum principle for optimal control problems. SIAM J. Control Optim. 28 (1990), 966–979.
J. Polchinski. Renormalization and effective Lagrangians. Nuclear Phys. B 231 (1984), 269–295.
M. Salmhofer. Renormalization: An Introduction. Springer, 1999.
Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon, B. Poole. Score-based generative modeling through stochastic differential equations. In International Conference on Learning Representations (ICLR), 2021. arXiv:2011.13456.
J. Sohl-Dickstein, E. A. Weiss, N. Maheswaranathan, S. Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In Proceedings of the 32nd International Conference on Machine Learning (ICML), 2015. arXiv:1503.03585.
C. Wetterich. Exact evolution equation for the effective potential. Phys. Lett. B 301 (1993), 90–94.
J. Yong, X. Y. Zhou. Stochastic Controls: Hamiltonian Systems and HJB Equations. Springer, 1999.